

Axolotl
A free, open-source framework for fine-tuning large language models, with fast-moving support for new model families and training techniques such as mixture-of-experts LoRA and multi-dimensional parallelism.
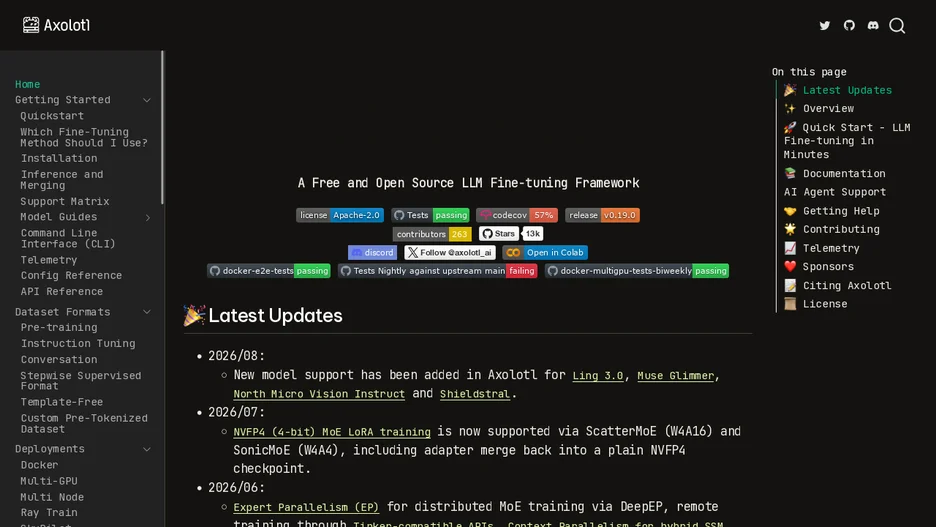
Axolotl is a free, open-source framework for fine-tuning large language models. Its recent updates add support for a wide and continually growing range of model families, including several generations of Qwen, GLM, Mistral and Gemma models, as well as hybrid state-space and mixture-of-experts architectures, keeping pace with new model releases as they appear.
On the training side, it supports low-bit mixture-of-experts LoRA fine-tuning through custom kernels, expert parallelism for distributed mixture-of-experts training, context parallelism for hybrid state-space models, sub-2-bit fine-tuning, mixture-of-experts quantization to reduce GPU memory use, reinforcement-learning methods such as an accelerated GRPO implementation, text-diffusion training, quantization-aware training, and combined context, tensor and fully sharded data parallelism within and across machines.
The project publishes detailed monthly notes on new model and technique support, giving a fairly direct view of which recent research ideas have been made available for practical fine-tuning.