

JANG
An adaptive mixed-precision quantization format and runtime for Apple Silicon MLX, positioned as a GGUF equivalent that keeps large models quantized in GPU memory while running at full Metal speed.
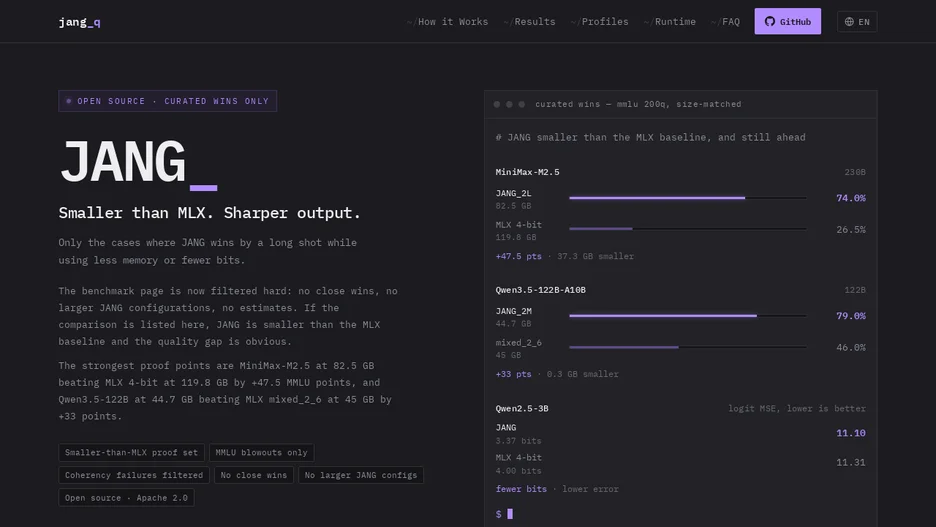
JANG is a quantization format and runtime for running large language models on Apple Silicon through MLX. It reports running very large mixture-of-experts models that MLX's own quantization cannot handle, including a model with hundreds of billions of parameters on a 128 GB Mac, by using bfloat16-aware quantization that avoids the float16 overflow MLX hits below 4-bit precision, and by streaming routed experts from disk with memory-mapped, cold-tier eviction for models larger than available RAM.
A companion native macOS app converts Hugging Face models into JANG formats through a five-step wizard with live logs, pre- and post-conversion verification, an in-app chat preview, and one-click publishing back to Hugging Face. The project reports benchmark comparisons against MLX's own quantization across several model families and sizes.
It installs as a pip package with an MLX extra; native support currently exists in one MLX-based chat app, with integration for others in progress.