

JevBench
A reproducible benchmark from Benchmark Heaven that ranks Jev-class typed decision models on intelligence, calibration, speed, and cost, with a published harness, scoring rules, and results.
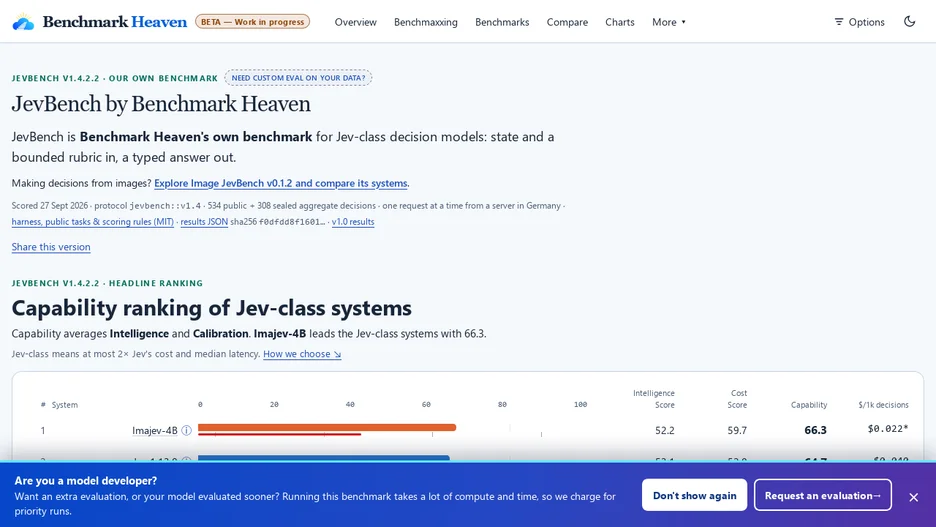
JevBench is a benchmark for Jev-class decision models, systems that take a state and a bounded rubric as input and return a typed answer, rather than open-ended text. It scores each system on intelligence and calibration to produce a combined capability score, and separately reports cost per thousand decisions and median latency, restricting the main ranking to systems within twice the cost and latency of the reference Jev model.
Each scoring run is versioned and reproducible: the published protocol version, the count of public and sealed aggregate decisions used, the server location, and a hash of the results file are all stated alongside the ranking, and the harness, public tasks, and scoring rules are released under the MIT license. A related benchmark separately compares systems that make decisions from images.
The site also lists general-purpose LLMs and other systems that fall outside the Jev-class cost and latency limits separately from the main ranking.