

KEDA GPU Scaler
A KEDA external scaler that reads GPU utilization and memory directly from NVIDIA's NVML library through a DaemonSet, so Kubernetes can autoscale GPU inference workloads without Prometheus or DCGM.
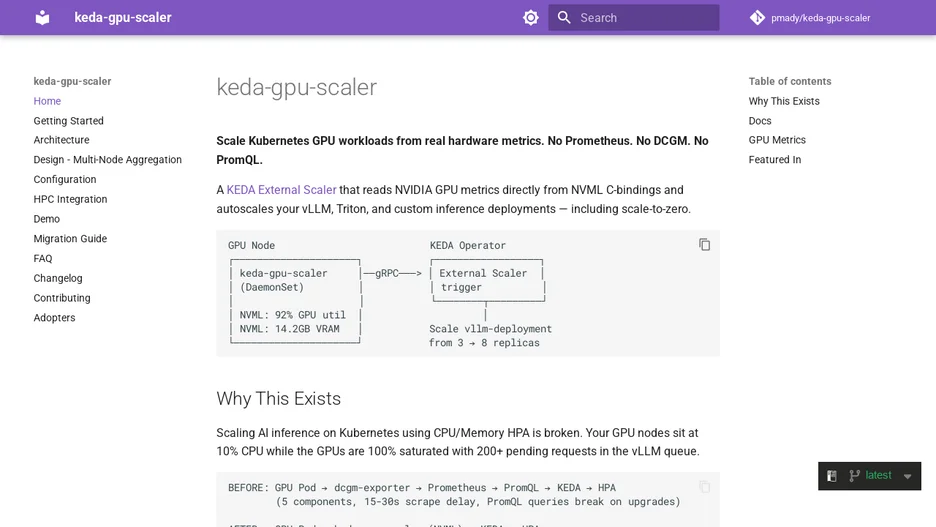
KEDA GPU Scaler addresses a gap in Kubernetes autoscaling: the standard Horizontal Pod Autoscaler only sees CPU and memory, so a vLLM or Triton pod can sit at 100 percent GPU use while showing low CPU. Rather than adding the usual dcgm-exporter, Prometheus and KEDA chain, a DaemonSet on each GPU node reads utilization, memory used, temperature and power draw directly through NVIDIA's NVML C bindings and serves them to KEDA's central operator over gRPC, so metric age is just the configured polling interval.
It cannot be built into KEDA's core scaler because KEDA is built with CGO disabled while NVIDIA's Go bindings require CGO, and because NVML needs node-level hardware access that only a per-node DaemonSet can provide. Prometheus metrics are available optionally. Each pod currently reports only its own node, so a multi-GPU-node cluster needs one ScaledObject per node or node selectors.
It is written in Go under Apache-2.0.