

MASArena
A benchmarking framework for single- and multi-agent LLM systems that pairs built-in datasets with evaluators, visual debugging of tool use and accuracy, and automated workflow optimization.
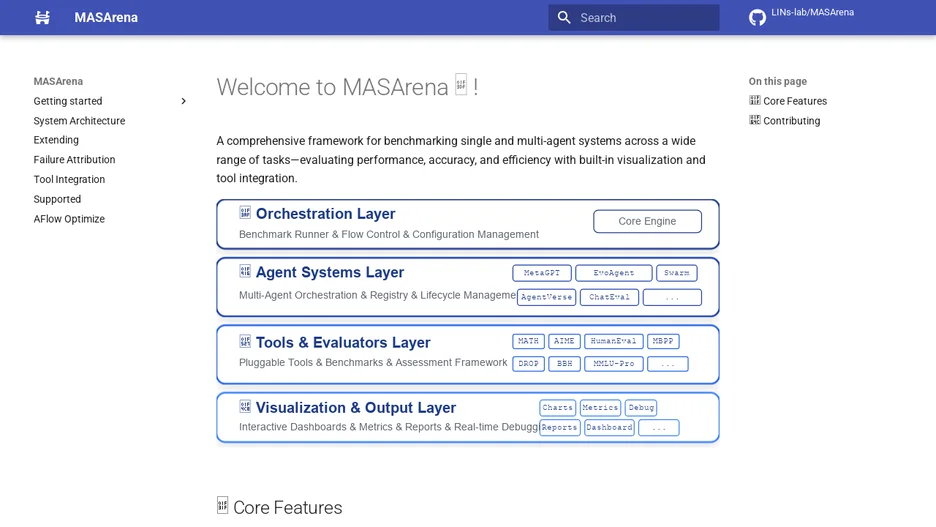
MASArena lets a developer swap agents, tools, datasets, prompts and evaluators to compare single-agent and multi-agent systems on a shared set of benchmarks, including math tasks such as AIME, code tasks such as HumanEval and MBPP, and reasoning tasks such as DROP, BBH, MMLU-Pro and HotpotQA. Supported agent systems range from a single agent up to named multi-agent strategies such as supervisor-based orchestration, swarm, AgentVerse, ChatEval, EvoAgent, Jarvis and MetaGPT.
It includes a visualization mode for inspecting agent interactions, accuracy and tool use, an automated workflow optimizer that uses LLM-driven evolutionary search to improve agent workflows, and a failure-attribution feature that identifies which agent caused a failure. New agents are added by subclassing without core changes, and new benchmarks by pairing a dataset with an evaluator. It sets up with uv and is configured through environment variables naming a model and an OpenAI-compatible API base.