

OpenRLHF
A high-performance, production-ready open-source RLHF framework built on Ray and vLLM, with a unified agent-based design for scalable reinforcement learning from human feedback.
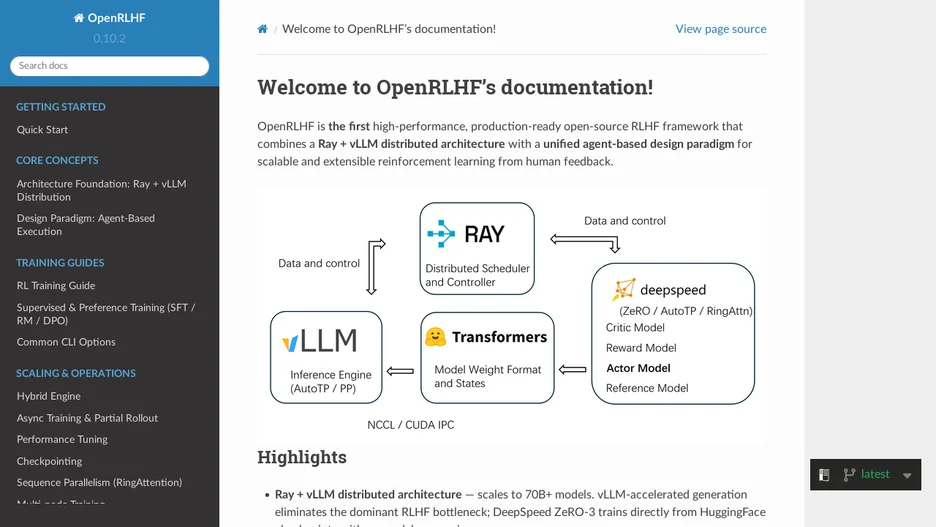
OpenRLHF is an open-source framework for reinforcement learning from human feedback (RLHF), combining a Ray and vLLM distributed architecture with a unified agent-based design for scalable training. It implements algorithms including PPO, REINFORCE++, GRPO and RLOO.
It covers a full RLHF pipeline: supervised fine-tuning, reward-model training, and reinforcement-learning training, including single-turn agents with custom reward functions and multi-turn agents for more complex environments, plus support for vision-language models with image inputs in both prompts and environment feedback. A newer Automodel-powered backend, Molt, scales training to hundreds of billions of parameters while keeping the same workflow, and LoRA and other performance-tuning options are supported.
Documentation is available in English, Chinese and Japanese. It is written in Python and released under the Apache-2.0 license.