

quantprobe
A tool that predicts whether a given GGUF language model will run on your hardware and how fast, then builds a quantized file customized to your machine and prints the exact llama.cpp command to run it.
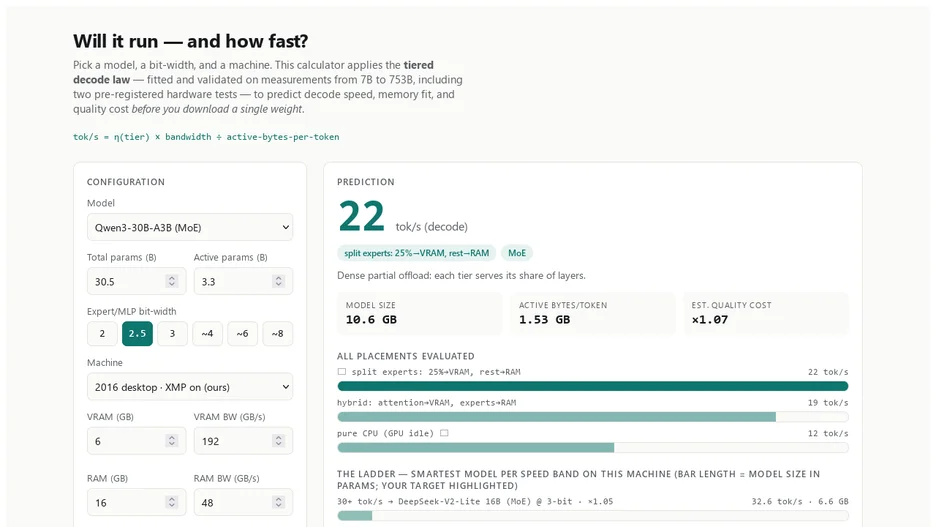
quantprobe probes each layer of a model to find where quality actually breaks, protects that band and compresses the rest, places the resulting file across VRAM, RAM and disk, and either prints the exact llama.cpp command to run it or launches it directly with a single command.
Every prediction is re-measured for speed after the fact, scored for quality with KL divergence, and run through 40 machine-checked business tasks, with results from a bench command optionally contributed to a shared public validation set; the project states that every claim is staked before measurement and that misses are published at the same size as hits. A binding-constraint line in its output reports whether a result is limited by disk or by memory bandwidth, so a user knows whether more RAM would actually help. It installs with pip, and an optional calibration step replaces spec-sheet assumptions with measured constants from the user's own hardware.