

ReinFlow: Fine-tuning Flow Matching Policy with Online Reinforcement Learning
A research codebase for fine-tuning flow-matching robot control policies with online reinforcement learning after an initial imitation-learning stage, evaluated on locomotion and manipulation benchmarks.
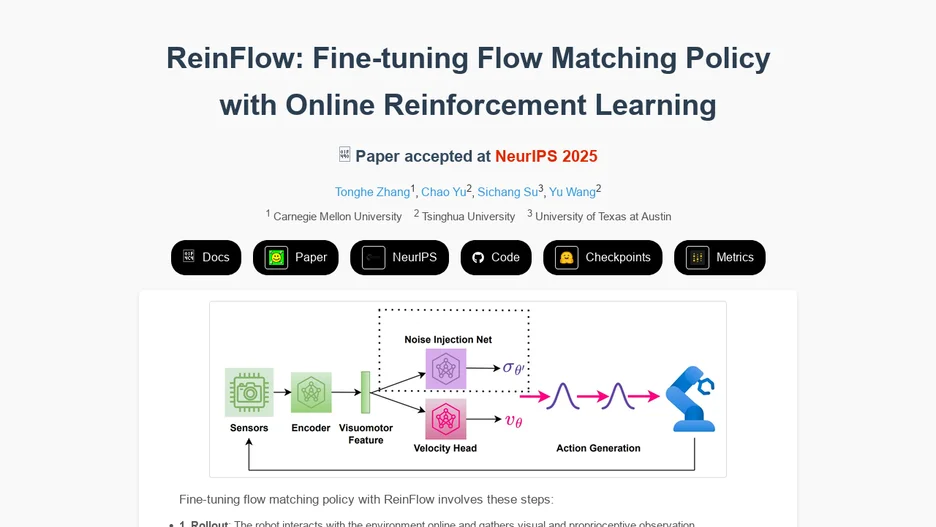
ReinFlow is the official implementation of a NeurIPS 2025 paper on fine-tuning flow-matching policies with online reinforcement learning. Its approach trains a flow policy first with imitation learning (behavior cloning), then improves it with online RL at any denoising step, using a noise-injection network and supporting 1-Rectified Flow, Shortcut Models and other ODE-defined policies.
The repository has since been extended to fine-tune vision-language-action models such as Pi0, Pi0.5 and GR00T N1.5, with reported results on legged locomotion (OpenAI Gym), state-based manipulation (Franka Kitchen) and visual manipulation (Robomimic), and links to related code and technical reports for LIBERO, MetaWorld and ManiSkill/Simpler evaluations.