

SlideFormer
A PyTorch runtime for full-parameter fine-tuning of large language models on a single GPU, which streams inactive layers between GPU memory, CPU RAM and optional NVMe storage.
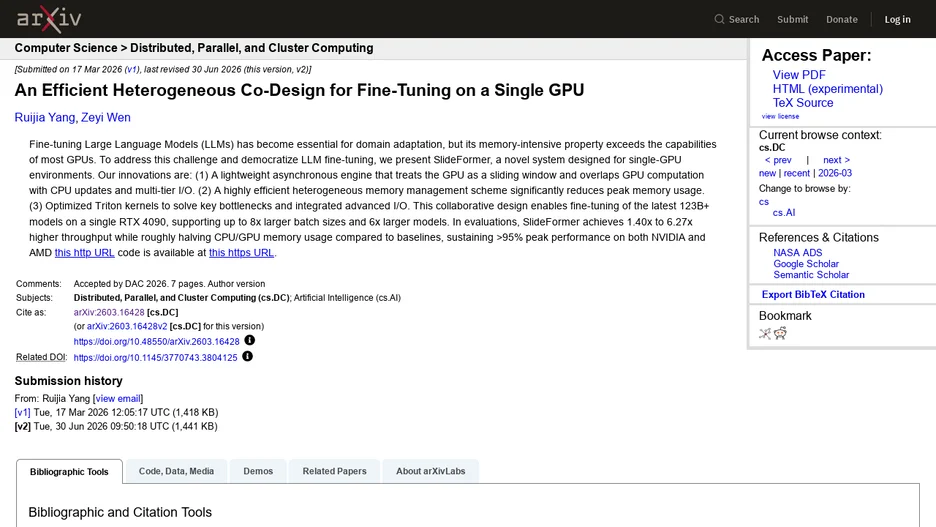
SlideFormer is a heterogeneous runtime for fine-tuning every parameter of a large language model using a single GPU. It keeps only a compact, active window of layers resident on the GPU at any time, while the persistent training state stays in CPU memory, and it schedules asynchronous transfers so GPU computation overlaps with CPU optimizer updates, format conversion and gradient movement across GPU memory, CPU RAM and optional NVMe storage.
The project reports 1.4 to 6.27 times higher throughput than comparable offloading approaches in its own evaluation, along with reduced peak GPU and CPU memory, larger supported batch sizes, and the ability to fully fine-tune models with more than 100 billion parameters on one commodity GPU. It was accepted at DAC 2026, and a multi-GPU extension is under active development.