

UniRL
A reinforcement-learning framework for post-training unified multimodal models, coordinating rollout generation, scoring and policy updates across pluggable trainers, rollout engines and algorithms.
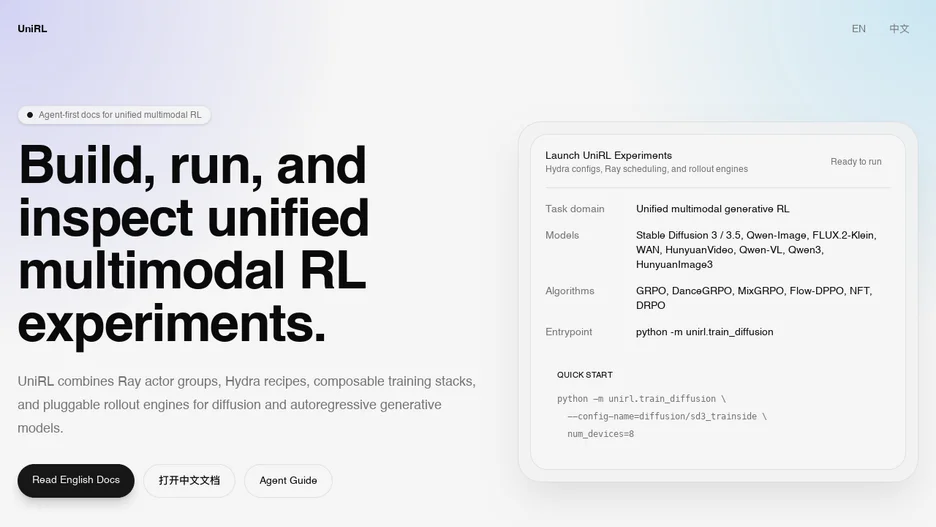
UniRL applies one reinforcement-learning post-training loop, generate samples, score them, compute advantages, update the policy, and sync weights back to rollout workers, across families of multimodal models. Training entrypoints load a Hydra example configuration and create a matching domain trainer, and RL trainers coordinate generation, scoring and updates across pluggable rollout engines, algorithms, model bundles and reward services.
The shared distributed runtime uses Ray's DevicePool, FSDP, a Transfer Queue, and LoRA or full-weight syncing. Supervised fine-tuning consumes supervised manifests, while asynchronous autoregressive and diffusion entrypoints overlap rollout with training on separate GPU slabs.
The project ships several algorithms proposed by its team, including Flow-DPPO, DRPO and CPPO, each with a tutorial and runnable example recipe, alongside reference algorithms such as GRPO, DiffusionNFT, DanceGRPO and MixGRPO.