

unsloth-buddy
A fine-tuning skill for Claude Code, Gemini CLI and other agent hosts that runs the whole LoRA fine-tuning lifecycle from a plain-language request: environment setup, data formatting, training, evaluation and export.
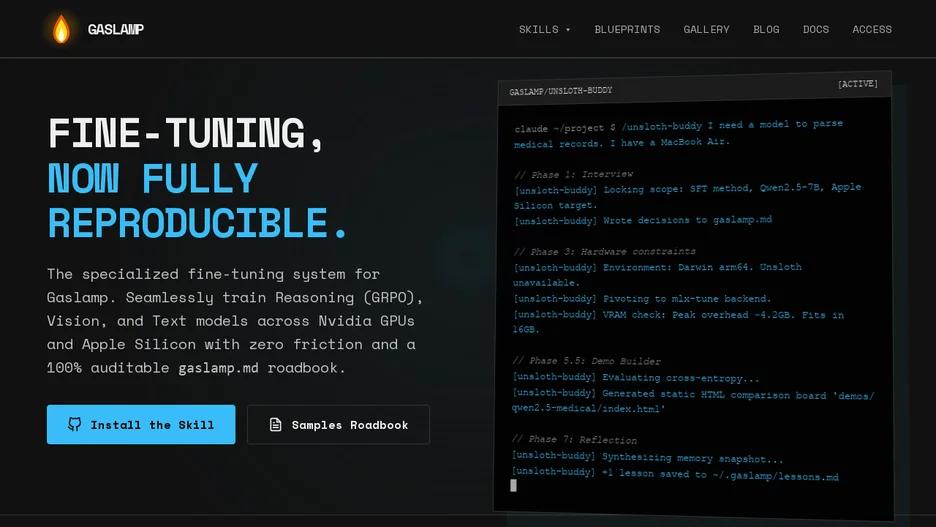
unsloth-buddy is an agent skill that turns a single conversational request, such as fine-tuning a summarization model from a set of customer support questions and answers, into a full fine-tuning run. It handles environment detection and setup, acquiring or reformatting data to match the trainer's expected schema, selecting a training technique such as SFT, DPO or GRPO based on the stated goal, training, running the fine-tuned adapter alongside the base model so the difference is visible rather than only reported as a loss number, and exporting to a chosen target such as Ollama, vLLM or the Hugging Face Hub.
It runs training through Unsloth on NVIDIA GPUs, through TRL with MPS or MLX natively on Apple Silicon, or on free cloud GPUs through a companion tool, and it is part of a larger AI development platform. It installs as a Claude Code plugin, a Gemini CLI extension, or by cloning the repository into any host that supports the Agent Skills standard, and it also runs post-hoc diagnostics on GRPO training logs.