

3DCodeBench
A benchmark that measures how well frontier AI models can write Blender Python code that procedurally builds a specific 3D object, scored on executability, image similarity, 3D shape distance and a language-model judge.
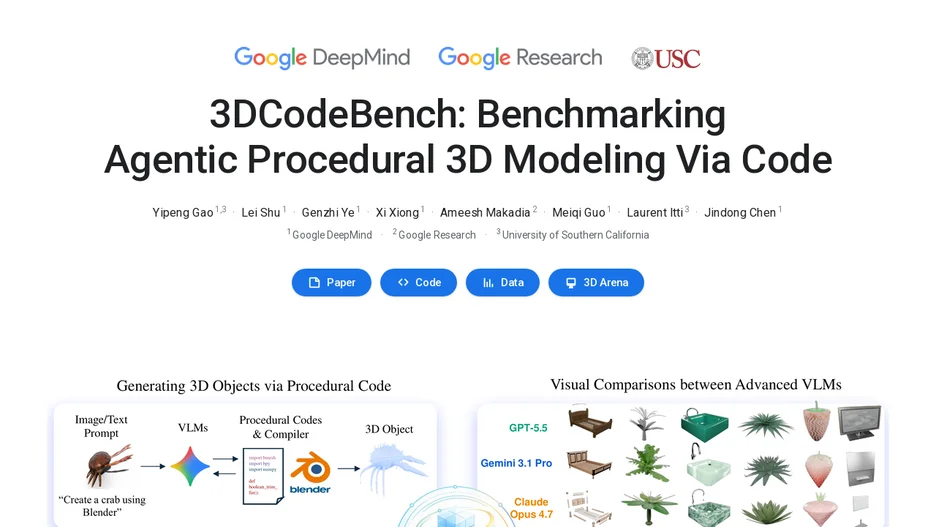
3DCodeBench measures agentic procedural 3D modeling through code: given a text description and a structured instruction, a model must write Blender 5.0 Python code that procedurally constructs a target 3D object. The benchmark covers 212 categories, such as chairs, plants, sea creatures, coral and kitchen hardware, each with a ground-truth factory script for comparison, and evaluates single-shot, multi-turn and full coding-agent settings.
Outputs are scored on whether the generated script actually executes, on image similarity using SigLIP-2 and DINOv3 embeddings, on 3D shape distance using Chamfer distance and Uni3D embeddings, and with a language-model-as-judge. The benchmark builds on the Infinigen procedural generation ecosystem: its categories and a larger companion corpus of 212 factories times 60 seeds, totaling 12,720 instances, are distilled from Infinigen and Infinigen Indoors procedural assets and converted into standalone Blender 5.0 scripts, each instance shipping two scripts, caption variants, multi-view renders and exported meshes.
The benchmark categories are hosted on Hugging Face rather than in the repository itself, and the project is accompanied by a paper and an online arena for comparing model results.