

AI Beat
A reproducible security evaluation workflow for generative AI, with one product testing an LLM or API's behavior under adversarial scenarios and a second extending that evaluation to a running agent's tool calls and file changes.
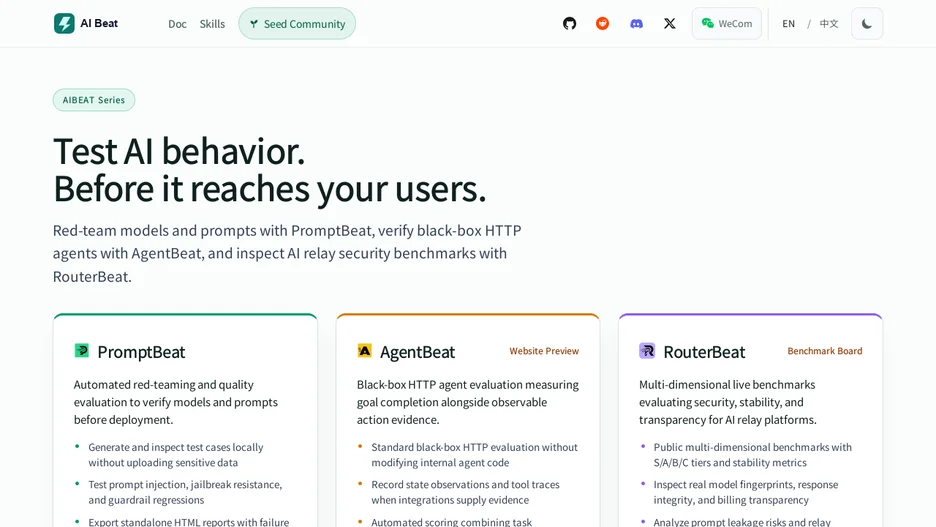
AI Beat is a security evaluation framework for generative AI that brings scenario design, adversarial test cases, target execution, judging, and evidence collection into one reproducible workflow. PromptBeat evaluates the behavior exposed by an LLM, a RAG application, an HTTP API, or an agent endpoint from the outside, in a black-box way, while AgentBeat extends the same evaluation to an instrumented agent's runtime, adding messages, tool calls, commands, file changes, and other runtime events as evidence.
The two products share the same scenario, case, judge, and report model, so an evaluation can start black-box and add runtime evidence only where the execution path matters. Each ships as a native Go command-line binary for Linux, Windows, and macOS (arm64 and x64), installed by a shell or PowerShell script that verifies checksums and prepares a Node.js and promptfoo runtime in a user cache without touching the global npm installation.