

ArxivExplorer
ArxivExplorer is a semantic search engine for arXiv papers that combines keyword and vector search, generates AI summaries and entity extraction for each paper, and tracks citations, without requiring a login.
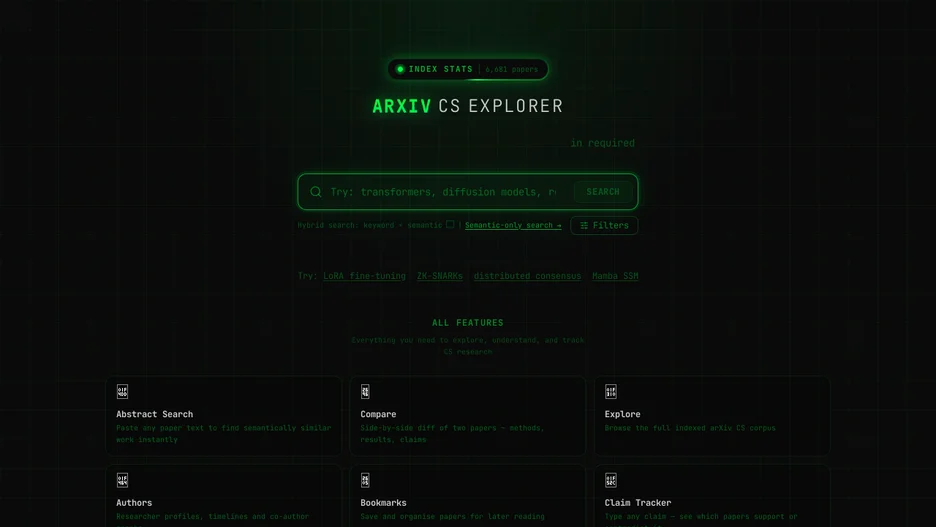
Search combines SQLite full-text search with a vector index for semantic similarity, letting a query match papers by meaning as well as exact terms, and results can be filtered by author, citation count, category and date range; a related-papers feature pre-computes the most semantically similar papers for each entry. Search results and embeddings are cached with different time-to-live windows to keep the service responsive.
AI-generated features include a short summary, key contributions, methods and limitations for each paper, extracted entities such as models, datasets and benchmarks, and a support-or-contradiction classification for scientific claims. Citation counts are enriched from Semantic Scholar, CrossRef and OpenAlex, and papers can be bookmarked, compared side by side and exported as JSON or BibTeX.
It is built with Next.js and Cloudflare Workers, and is written in TypeScript.