

Awesome RAG Production
A curated, weekly-audited list of tools, frameworks and practices for building retrieval-augmented-generation systems at production scale, with reference architectures, real case studies and source-tagged benchmark numbers.
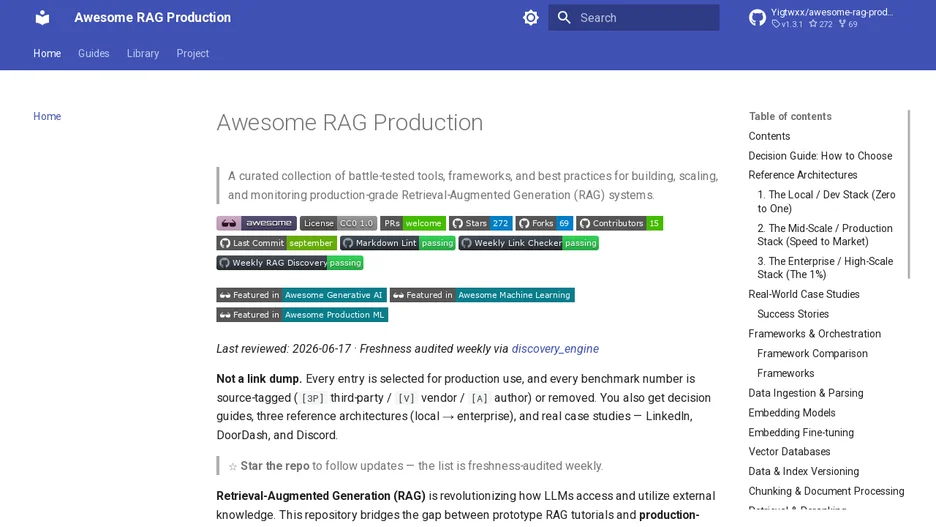
Awesome RAG Production is built around production use rather than prototype tutorials: every listed benchmark number is tagged as third-party, vendor or author-reported, or removed if it cannot be tagged, and the list states it is freshness-audited on a weekly basis. Beyond the tool listings, it includes a decision guide for choosing a framework, vector database, embedding model, reranker and chunking strategy for a given scale, three reference architectures ranging from local to enterprise deployment, and real case studies from companies including LinkedIn, DoorDash and Discord.
Category sections cover the full production pipeline: data ingestion and parsing, embedding models and their fine-tuning, vector databases and index versioning, chunking, retrieval and reranking, query transformation and routing, agentic and multimodal RAG, structured and SQL RAG, evaluation and benchmarking, observability and tracing, deployment and serving, caching and performance, security and compliance, LLM gateways, and cost management, alongside pitfalls, datasets, and further tutorials.