

BenchBoard
A source-linked index of published AI model benchmark scores that keeps each score tied to its model release, benchmark variant and evaluation setting, without combining results from different harnesses into an invented composite score.
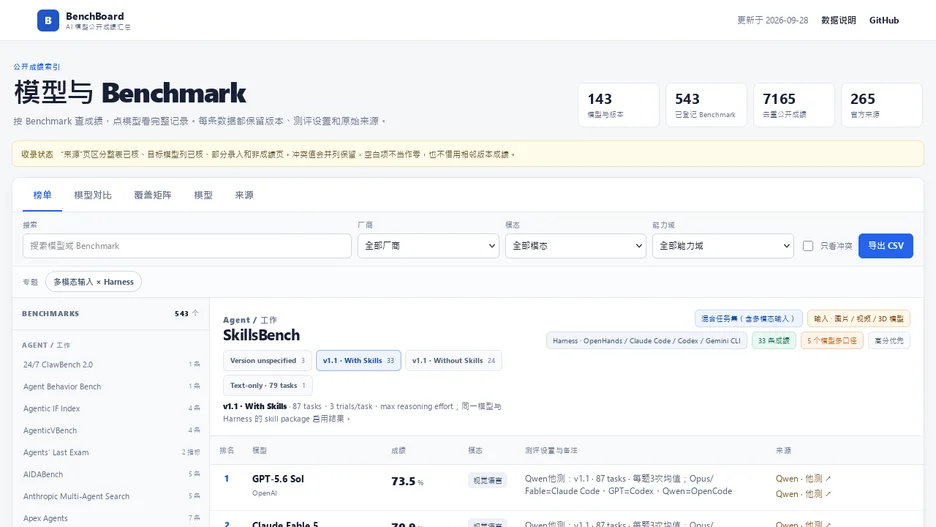
BenchBoard indexes benchmark results that AI model providers, benchmark maintainers and technical reports have already published, rather than running its own evaluations. Every recorded score keeps its model release, the specific benchmark variant, the evaluation setting, and a link back to the original source, such as a release page, model card, paper or official leaderboard; results from different benchmark harnesses or versions are kept separate rather than merged into a single number.
Opening a model's page shows every recorded result and setting for that release, along with a coverage matrix describing how completely each source has been checked and where published values conflict. Up to three model releases can be compared side by side, the full index can be browsed or searched in the browser, and a filtered table can be exported as CSV or shared by its URL.
The site is built with JavaScript and licensed under MIT.