

Cache-DiT
A PyTorch-native inference engine built on Diffusers that adds hybrid cache acceleration and parallelism, quantization, and CPU offload for diffusion transformer (DiT) image and video models.
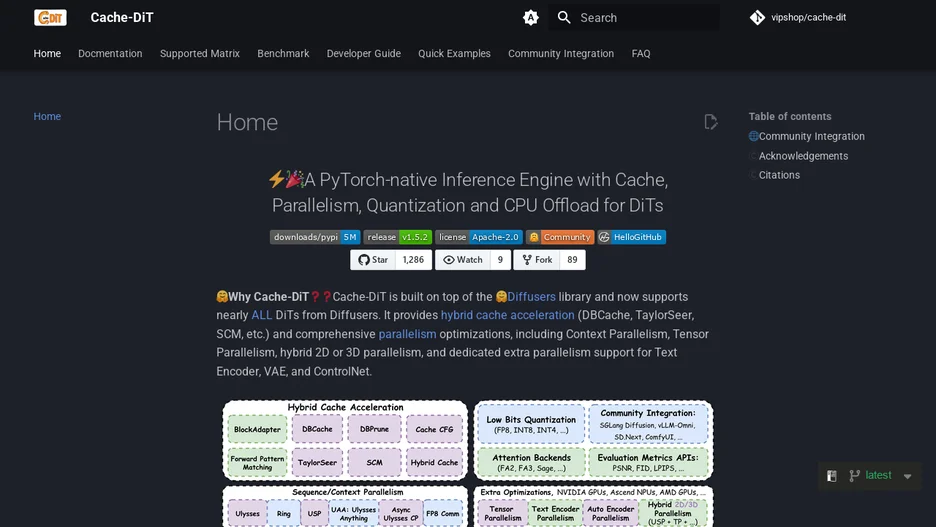
Cache-DiT is a PyTorch-native inference engine, built on top of the Diffusers library, that supports nearly all diffusion transformer (DiT) pipelines available in Diffusers. It provides hybrid cache acceleration methods such as DBCache, TaylorSeer, and SCM, alongside parallelism optimizations including context parallelism, tensor parallelism, hybrid 2D or 3D parallelism, and dedicated support for parallelizing the text encoder, VAE, and ControlNet separately.
It is compatible with model compilation, CPU offloading, and quantization, and integrates with SGLang Diffusion, vLLM-Omni, TensorRT-LLM, and ComfyUI, running natively on NVIDIA GPUs, Ascend NPUs, and AMD GPUs. More than 40 DiT pipeline families and over 120 model variants from Diffusers are supported, including FLUX, FLUX.2, Qwen-Image, Z-Image, SD3, and PixArt, each noted for which of caching, parallelism, quantization, and offload it supports.
Full documentation and a technical report are published alongside the code.