

ClawBench: Can AI Agents Complete Everyday Online Tasks?
An open-source benchmark that evaluates browser AI agents on everyday online tasks such as booking travel, ordering food and applying for jobs, across a set of live websites.
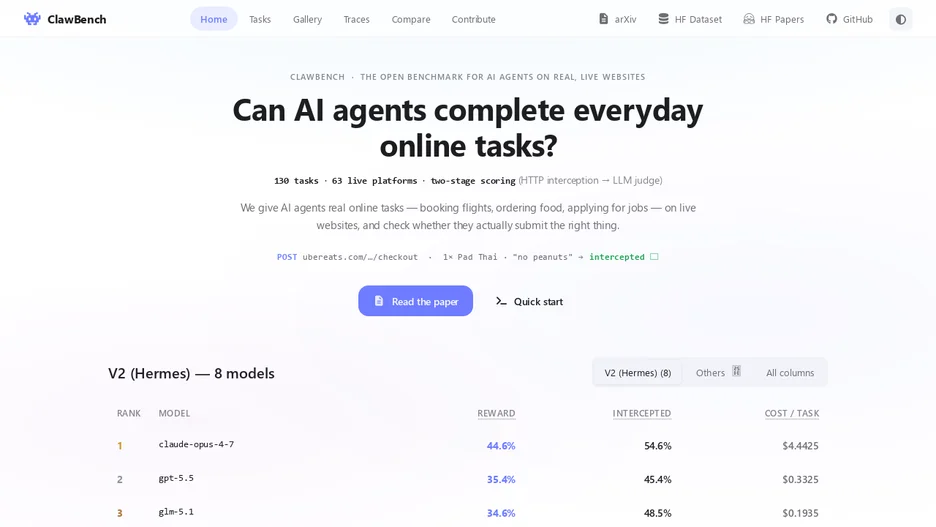
ClawBench evaluates AI browser agents against 281 everyday tasks across 163 live websites, spanning 15 life categories such as booking travel, ordering food, applying for jobs and managing email. It measures end-to-end task success with a five-layer recording pipeline and an agentic evaluator that compares each run against human reference solutions, and its historical V1 paper evaluation found that the strongest agent tested completed about one in three tasks.
It installs as clawbench-eval through uv, pipx or pip, providing commands to run, batch-run, rescore, analyze and reproduce evaluations, with Docker-isolated harnesses for each run. A public leaderboard tracks scores by corpus, harness and scoring rubric, and the underlying tasks, rubrics and metadata are downloadable from Hugging Face.