

CUBRID Python Cookbook
A collection of production-ready Python examples for the CUBRID database, with five-minute quickstarts for FastAPI and SQLAlchemy, a Java-to-Python migration guide, copy-and-customize service templates, and benchmark-backed performance patterns.
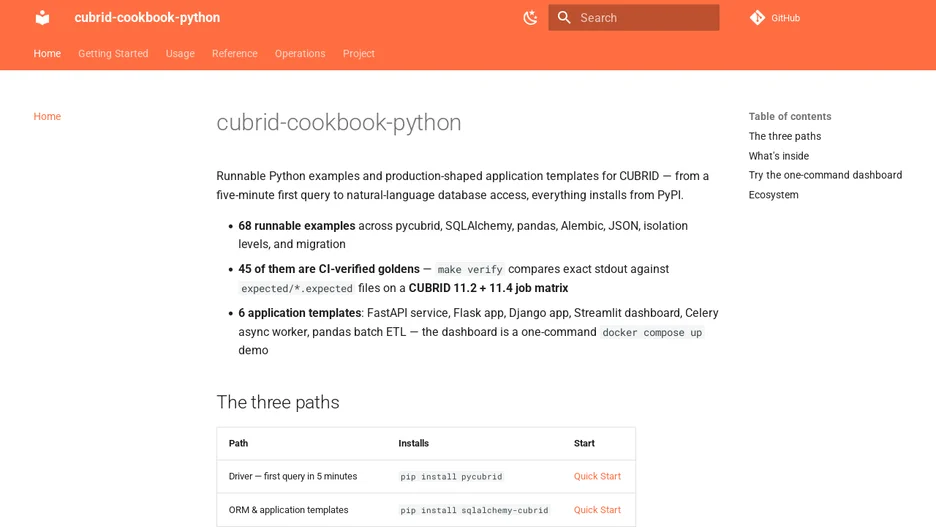
This cookbook takes a developer from a first CUBRID connection to a production API, with quickstarts that get a CUBRID-backed FastAPI or SQLAlchemy app running under Docker in about five minutes, and a side-by-side Java JDBC to Python migration guide covering connections, CRUD through both the DB-API and an ORM, transactions and batch operations.
Production templates cover a FastAPI REST service with SQLAlchemy and Docker, Flask and Flask-SQLAlchemy patterns, a minimal Django app, a Celery-based async worker, a pandas batch-ETL pipeline, a Streamlit dashboard, and an AI-agent template combining a state store, an MCP toolchain and RAG metadata.
A performance section documents benchmark-backed patterns such as fetch optimization and batched bulk inserts, and a pitfalls section lists seven common anti-patterns, including reserved-word collisions and auto-commit differences, that the project says cause real production issues.