

cupel
A tool for scoring local and cloud language models against custom prompts using a configurable judge model, with a bundled web dashboard for building prompts and browsing a leaderboard.
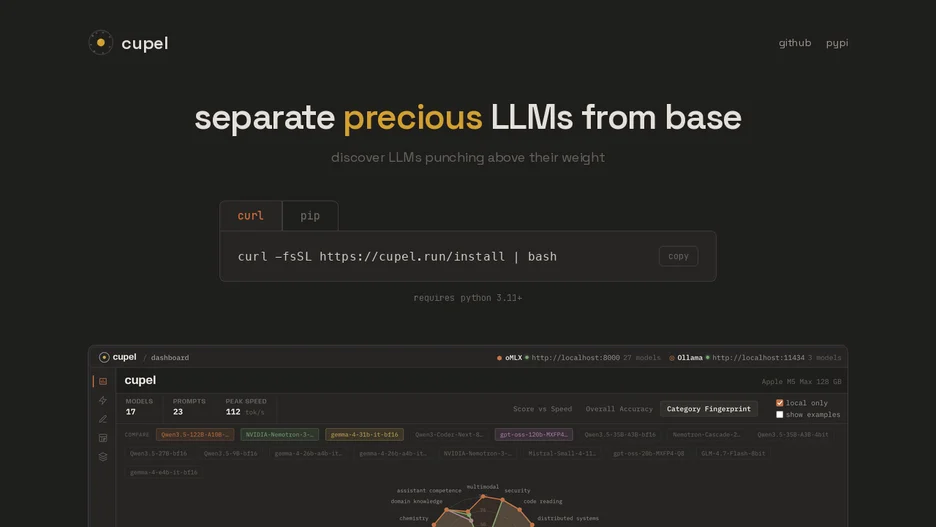
cupel lets a developer describe what they want to test, and an LLM drafts the prompt text and a 0 to 3 rubric for judging replies. Runs can target local providers such as MLX, Ollama, LM Studio and SGLang alongside cloud providers including OpenRouter, Anthropic and OpenAI, and a chosen judge model scores every response against the rubric with a written justification.
The bundled dashboard shows a leaderboard of score against speed, tokens-per-second and response time per model, and per-category breakdowns. It handles multi-turn conversations with injected tool results and separates a model's reasoning block from its final answer before judging only the answer. Each run is saved as JSON with the model, judge, prompt and per-prompt scores, and results can be sorted, tagged, muted or expanded for inspection.