

DeepEval
An open-source evaluation framework for large language model applications, agents and RAG pipelines, similar to Pytest but specialized for scoring outputs with metrics such as answer relevancy, hallucination detection and task completion.
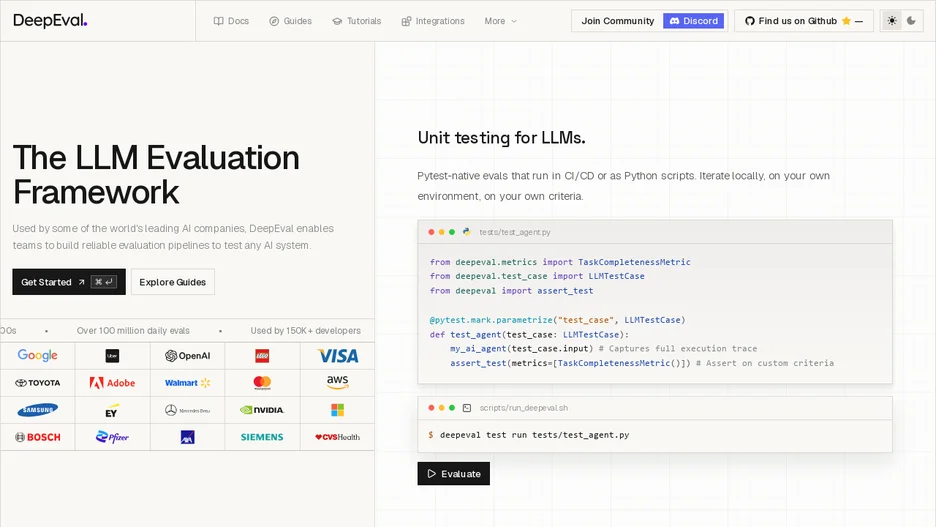
DeepEval is an open-source framework for evaluating large language model systems, agents, RAG pipelines and chatbots, comparable to Pytest but specialized for unit testing LLM applications. It runs evaluation metrics using LLM-as-a-judge techniques and other NLP models locally on the user's own machine.
It can evaluate an LLM application end to end as a black box, score a complete agent trajectory across every decision and action, or check individual steps such as LLM calls, tool use, retrieval and sub-agent handoffs. Metrics include G-Eval, a research-based LLM-as-a-judge metric for custom criteria; DAG, a graph-based deterministic LLM-as-a-judge metric builder; and agentic metrics such as task completion, tool correctness, goal accuracy, step efficiency and plan adherence.
It integrates with frameworks such as LangChain and with OpenAI- or Claude-based applications, and is written in Python.