

DeepSWE
A benchmark of 113 original, long-horizon software-engineering tasks across five languages, drawn from active open-source repositories, for measuring how well frontier coding agents perform on real engineering work.
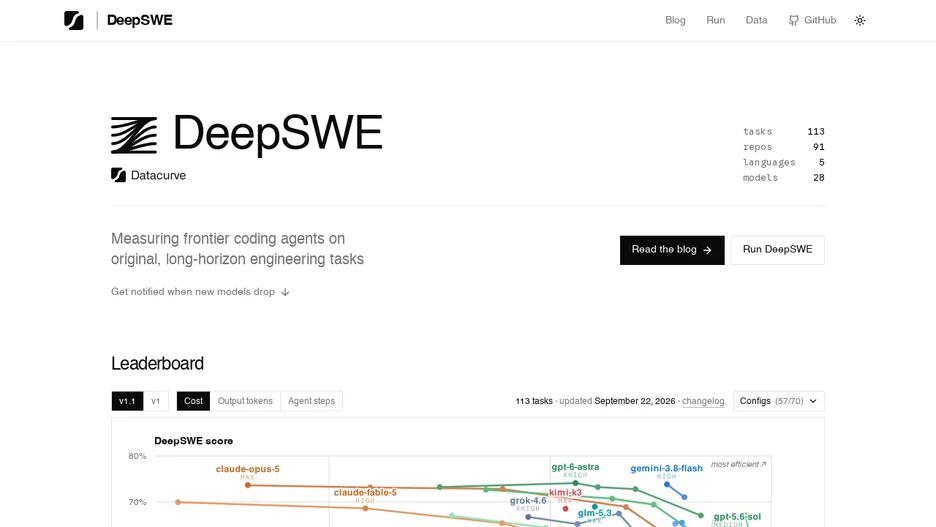
DeepSWE is a benchmark for measuring coding agents on original, long-horizon software-engineering tasks taken from active open-source repositories, covering TypeScript, Go, Python, JavaScript and Rust. Each task ships as a self-contained bundle: metadata about the repository, base commit and language; the prompt the agent sees; a Dockerfile reproducing the environment; held-out tests and a grader; and a reference solution kept hidden from the agent and used only for offline spot-checking.
Grading runs in an isolated environment, using a separate verifier environment so the agent cannot see the tests it will be graded against, and it accepts any solution whose observable behavior is correct regardless of internal structure. It runs through Pier, a Harbor-compatible framework for sandboxed coding-agent evaluations that adds per-agent network allowlists for tasks that must otherwise block all outbound traffic.