

GenieX
An on-device generative AI inference runtime for Qualcomm Snapdragon devices, running GGUF or pre-compiled models on the Hexagon NPU, Adreno GPU or CPU.
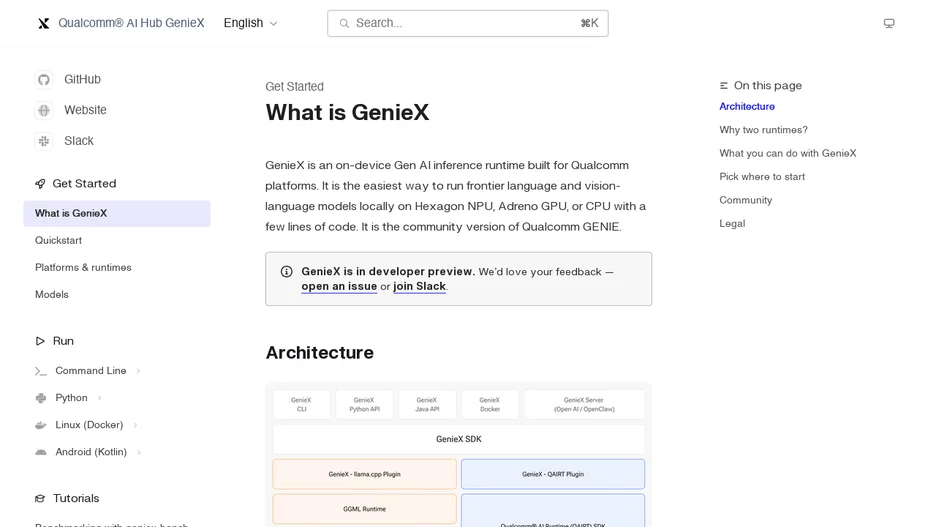
GenieX is an on-device generative AI inference runtime for Qualcomm devices. It runs almost any GGUF model from Hugging Face, ModelScope or Docker Hub, or a pre-compiled bundle from Qualcomm AI Hub, locally on the Hexagon NPU, Adreno GPU or CPU. A single underlying C SDK is exposed through a CLI, Python, Kotlin/Java, Docker and an OpenAI-compatible server, and the project is the community version of Qualcomm's GENIE.
It runs only on Qualcomm Snapdragon hardware, with quickstarts for Windows ARM64 compute devices such as Snapdragon X and X Elite, Android mobile devices such as Snapdragon 8 Elite, and Linux ARM64 IoT devices such as Dragonwing QCS9075. Its Python API mirrors the Hugging Face transformers pattern of from_pretrained() followed by .generate().
The geniex serve command starts a local OpenAI-compatible API after pulling a model, so existing OpenAI-client code can talk to a locally running model without modification.