

GPUStack
An open-source GPU cluster manager that configures and orchestrates inference engines such as vLLM and SGLang, and lets a team launch SSH-accessible GPU instances on demand.
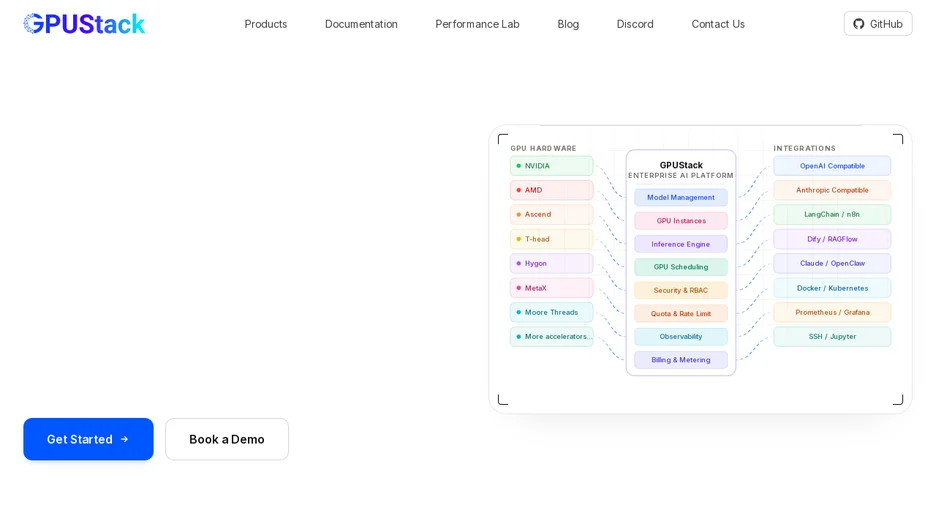
GPUStack manages GPU clusters across on-premises servers, Kubernetes clusters and cloud providers for AI model serving and GPU instance provisioning, automatically configuring pluggable inference engines such as vLLM, SGLang and TensorRT-LLM, or a custom engine.
It offers pre-tuned modes for low latency or high throughput, extended KV cache systems such as LMCache and HiCache to reduce time-to-first-token, and speculative decoding methods including EAGLE3, MTP and N-grams. SSH-accessible GPU instances can be launched on demand for development, fine-tuning or interactive work, alongside automated failure recovery, load balancing, authentication and access control, with monitoring surfaced through Grafana and Prometheus dashboards.
It supports industry-standard APIs for LLM, voice, image and video models, is written in Python, and is licensed under Apache-2.0.