

hal0
A self-hosted home AI inference platform for AMD Strix Halo hardware that turns a Linux box into an OpenAI-compatible endpoint for chat, embeddings, reranking, transcription, speech and image generation.
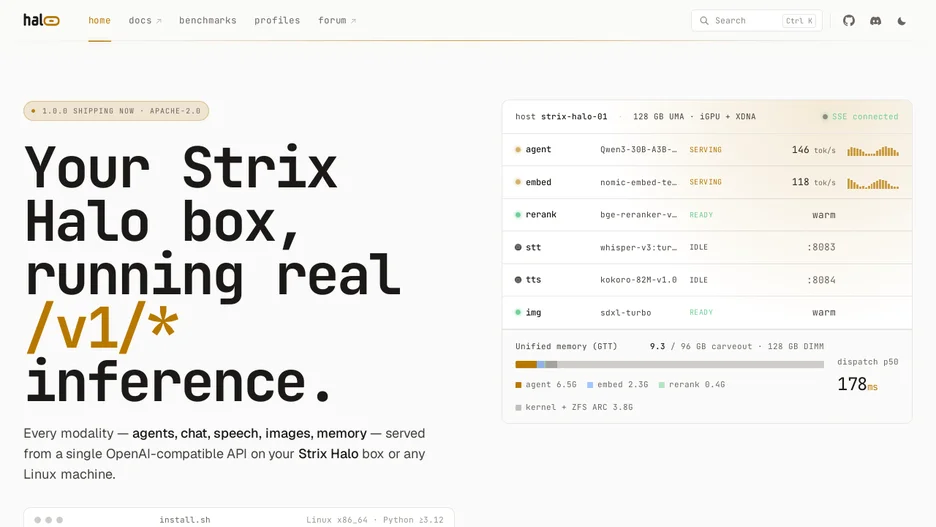
hal0 turns a Linux machine, ideally a Ryzen AI Max+ 395 with 128 GB of unified memory, into a private, OpenAI-compatible inference appliance serving chat, completions, embeddings, reranking, transcription, speech and image generation on one API surface, with no per-token billing.
Every inference workload runs as its own podman container under a systemd slot service unit, and a single API process on port 8080 is the sole control plane: it owns slot state machines, dispatches requests to the right slot, and serves a web dashboard covering models, image generation queues and memory. Declarative stacks bundle a slot, profile and model set and apply them atomically.
Installation is a single shell script that asks where models should live, optionally takes a Hugging Face token, seeds every capability slot, downloads a steward model, and starts the API; there is no separate first-run wizard afterward.