

JEVfire
A CUDA technique for large language models that batches many independent structured-output decisions into one parallel pass over a shared prompt, instead of generating each field as separate constrained JSON.
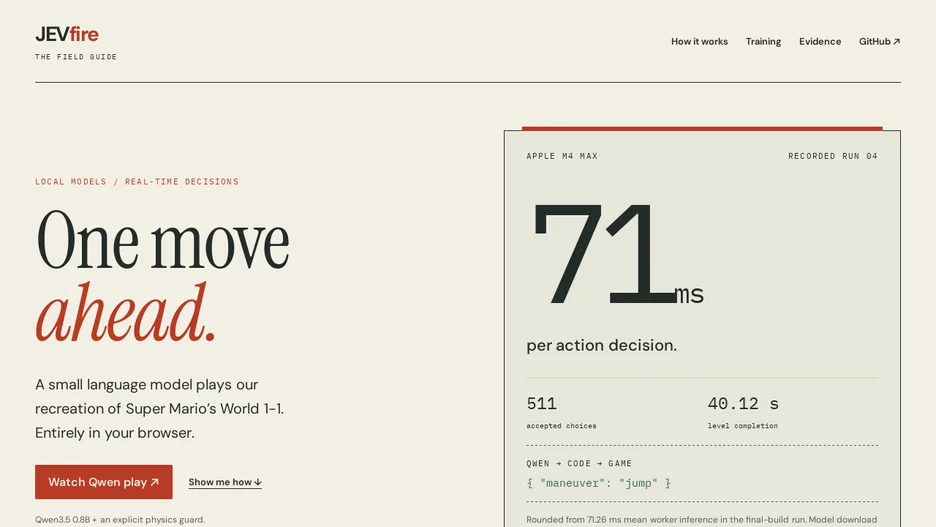
JEVfire assigns typed variables from a finite set of choices by batching independent fields through vLLM for parallel execution, reusing a shared instruction and context prefix when the inference engine's cache allows it. It scores single-token labels with the pretrained model's own language-model head rather than retraining or adding a second model, maps the winning tokens to the allowed values, and assembles the resulting JSON in application code, so the model cannot invent fields or out-of-set values, though it can still choose an incorrect allowed value.
The project reports substantially faster structured-output generation than grammar-constrained JSON generation on synthetic multi-field tasks, measured on both consumer and datacenter GPUs, and includes a browser-based game demo and reproducible benchmarks alongside a vLLM-compatible API.
It is written in JavaScript and released under the MIT license.