

KVarN
A native vLLM attention backend that quantizes the KV cache to fit three to five times more context in the same memory, without a calibration step and without changing the served model.
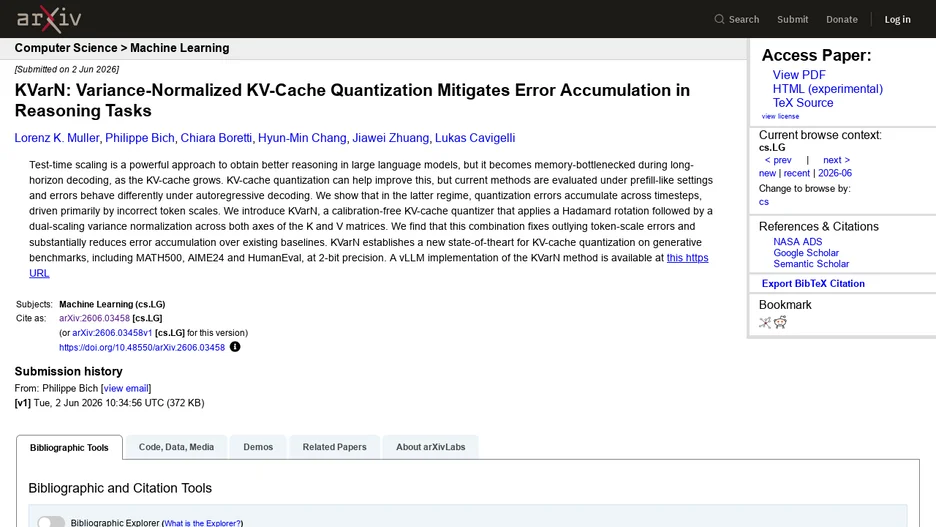
KVarN is a KV-cache quantization method for vLLM aimed at agentic and long-context workloads. Existing quantization approaches trade throughput for extra capacity or lose accuracy at low bit widths; KVarN is designed to keep both, matching FP16 accuracy while beating FP16 throughput and multiplying KV-cache capacity, according to results on Qwen3-32B.
It is calibration-free and plug-and-play: it adds to an existing vLLM deployment as a single flag, with no model changes. It runs in float16 compute, with a tile size equal to the vLLM block size; both a 128 (default) and a 64 tile size are supported, trading capacity for finer quantization granularity.
It ships as a vLLM fork, installed from the upstream precompiled wheel, with its kernels written in Triton and compiled just in time at runtime.