

Laya-MLX
A native Apple Silicon MLX runtime for Laya's typed decision models, answering short structured questions in single-digit milliseconds with no text generation.
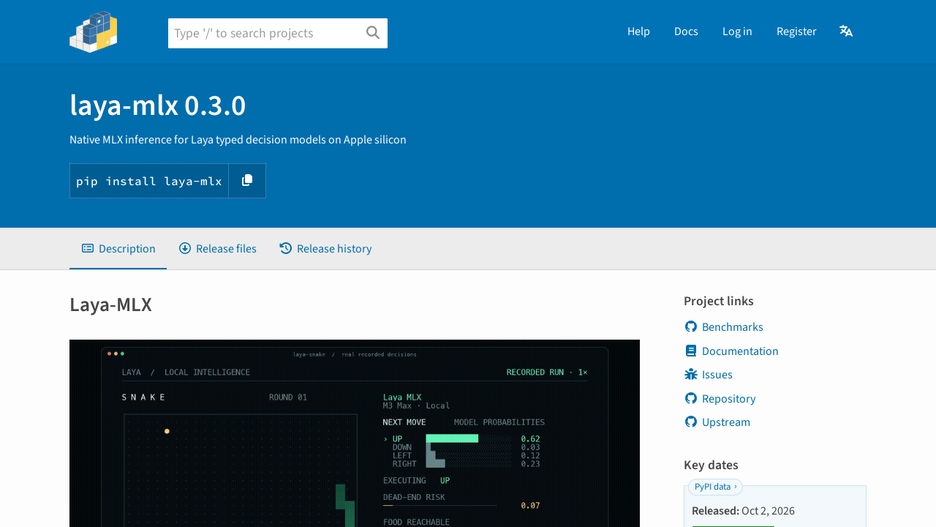
Laya-MLX runs a typed-decision model, which answers a defined question such as which department should handle a request by choosing from given criteria, rather than generating free text, and produces zero output tokens per call. On an M3 Max it measures a median 13.4 milliseconds end-to-end for a short English decision and 7.4 milliseconds with its multilingual checkpoint, using local MLX inference with no PyTorch, Transformers runtime, or cloud API involved.
The package includes a terminal Snake game demo that calls the model on every move as a way to demonstrate latency and stability under real-time constraints, along with a separate one-question API benchmark used for the headline latency figures.
It requires Apple Silicon, Python 3.11 or newer, and macOS 14 or newer, and is distributed under the Apache-2.0 license.