

llama_ros
A set of ROS 2 packages that bring llama.cpp and llava.cpp into robotics projects, letting a robot run GGUF language and vision-language models, including grammar-constrained output and real-time LoRA adapter changes.
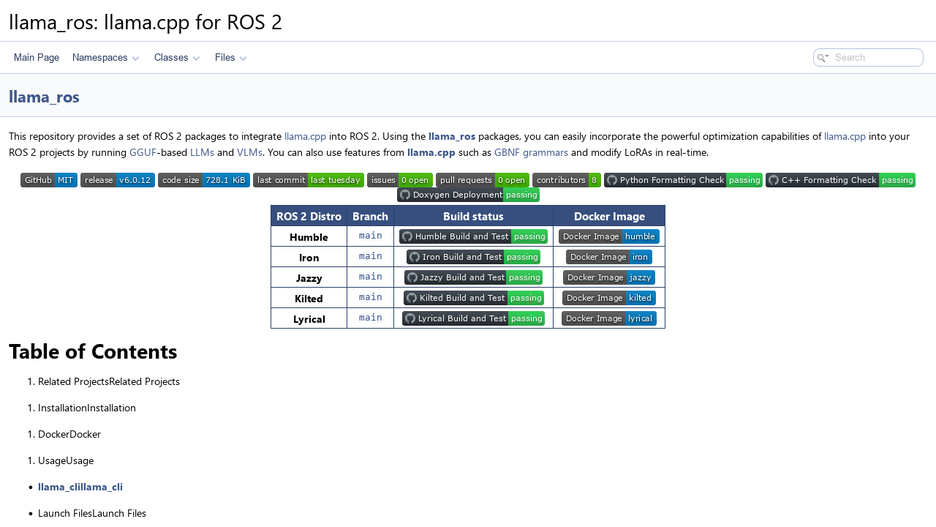
llama_ros integrates llama.cpp and llava.cpp into ROS 2, so a robot can run GGUF-based large language models and vision-language models directly as part of its software stack. It supports llama.cpp features such as GBNF grammars for constrained output and modifying LoRA adapters at runtime, and it builds with CUDA support for GPU inference.
The project ships a command-line tool, launch files, ROS 2 parameters, speculative decoding, message types, ROS 2 clients and a LangChain integration. Related projects built on it include chatbot_ros, which combines it with whisper_ros for spoken conversation controlled by a state machine, and explainable_ros, which stores robot logs in a vector database and uses retrieval-augmented generation to answer questions about a robot's behavior.