

llamactl
A unified manager and router for llama.cpp, MLX and vLLM model instances, with a web dashboard, a built-in model downloader, and OpenAI- and Anthropic-compatible routing across multiple running models.
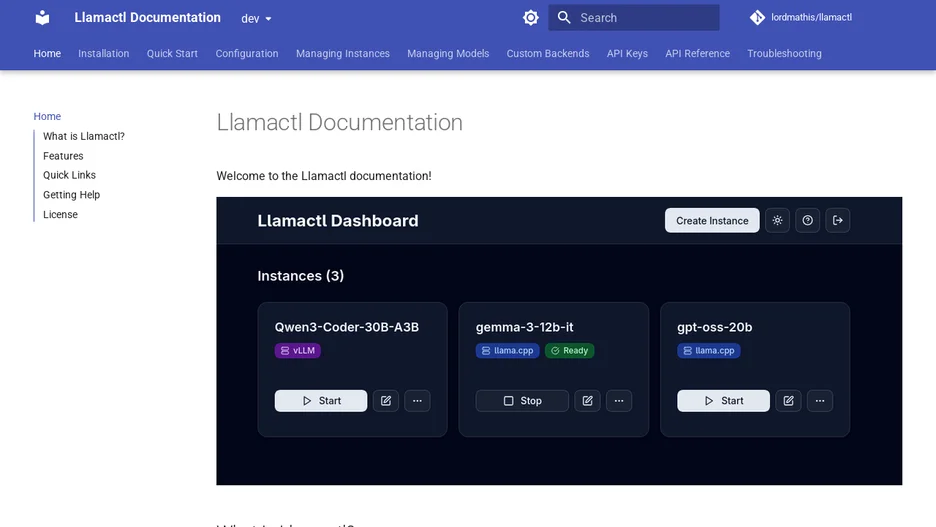
llamactl manages multiple model-serving instances across llama.cpp, MLX and vLLM, plus any other OpenAI-compatible custom backend, downloading GGUF and Safetensors models directly from Hugging Face and loading them on demand. A React-based web dashboard shows instance health and logs, and llama.cpp's router mode can serve several models from one instance.
Idle instances time out automatically, least-recently-used instances are evicted under memory pressure, and instance groups can cap how many run at once. Requests are routed to the correct backend by instance name through OpenAI chat-completions-compatible and Anthropic-messages-compatible endpoints, and instances can run in Docker with GPU passthrough or on remote hosts managed from one central dashboard.
It is written in Go and MIT licensed.