

llm-benchmarks
A Ruby command-line tool and companion website that runs AI language models against code-generation and program-repair benchmarks, then publishes the rankings and metrics.
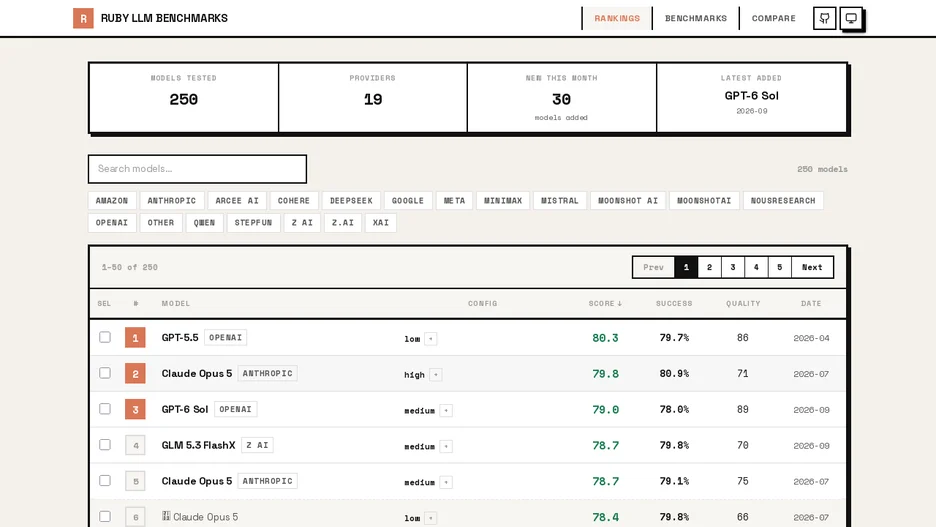
llm-benchmarks is a set of Ruby coding benchmarks for evaluating AI language models. It includes performance benchmarks (CSV data processing, graph shortest path, LRU cache implementations, run-length encoding) and program-fixer benchmarks (calendar system debugging, parking garage logic, school library management, vending machine state handling).
A command-line tool reads model capabilities from RubyLLM and OpenRouter, runs models against the benchmark suite, and can automatically generate reasoning or thinking variants for models that support them. A separate script carries the structured results through to an accompanying website that shows rankings and detailed metrics. Ruby 3.4 or newer is required to run it.