

LLM Compressor
A library for quantizing and compressing large language models for deployment with vLLM, covering weight, activation, KV-cache and attention quantization with Hugging Face integration.
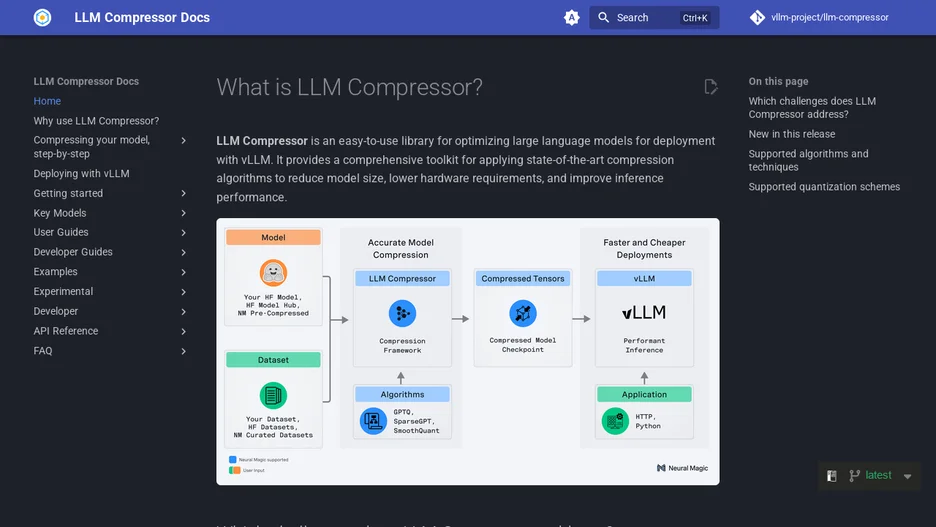
LLM Compressor is a library for optimizing models for deployment with vLLM. It provides a set of quantization algorithms and transforms for weight, activation, KV cache and attention quantization, integrates directly with Hugging Face models and repositories, and saves output models in the compressed-tensors format that vLLM can load.
It supports distributed data-parallel and disk-offloading workflows for compressing very large models on limited hardware. Recent releases added a Triton-based GPTQ kernel with layer batching for large speedups on mixture-of-experts models, and expanded MSE and iMatrix observer support for FP4 quantization, including a Triton kernel for the MSE observer's scale grid search that supports INT, FP4, FP8 and FP16/BF16 formats.
It installs as a Python package and is licensed under Apache-2.0.