

memra
A Rust and CUDA LLM inference engine tuned specifically for NVIDIA's Blackwell-generation GPUs (RTX PRO 6000, RTX 5090, B200), with an OpenAI-compatible server and hardware-specific low-bit quantization support.
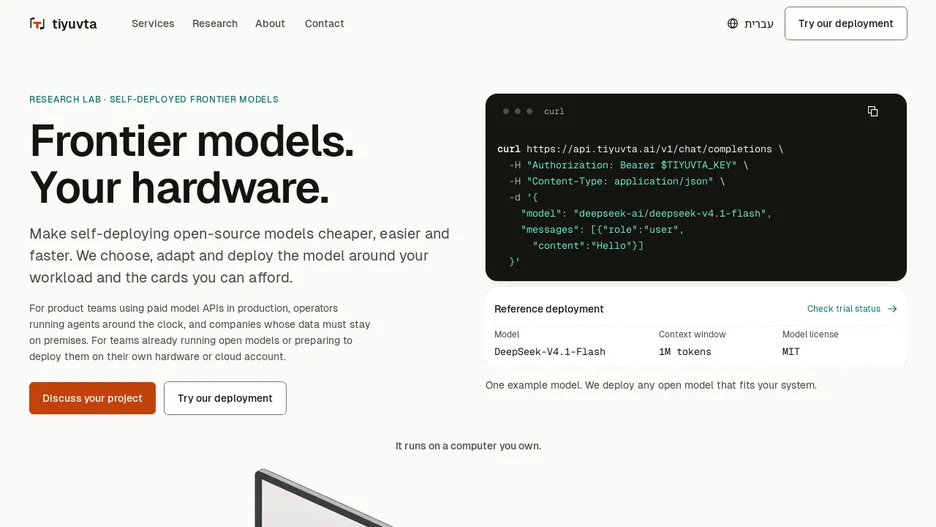
memra is a from-scratch inference engine, kernels, quantization arithmetic, speculative decoding and serving, built for Blackwell-generation NVIDIA GPUs, deliberately narrow in scope rather than aiming for broad hardware or architecture coverage. It serves an OpenAI-compatible chat completions API, with Anthropic-style converse support, and supports NVFP4 and mixed-precision quantization schemes tuned per model and per piece of hardware.
A prebuilt installer targets Linux x86_64 with an NVIDIA driver supporting the CUDA 13 runtime, verifies its checksum, and does not require nvcc; a kernel-check command confirms the install. Serving a model is a single command naming a Hugging Face checkpoint and quantization variant, after which the server listens locally and accepts streaming chat completions. The project is the research engine behind a separate hosted inference API and deployment service operated by the same lab, which the project states feeds tuning back into memra.