

MTPLX
A native macOS app and command-line tool that runs local language models such as Qwen 3.8 on Apple Silicon using the models' own multi-token prediction heads for faster decoding, exposing an OpenAI- and Anthropic-compatible local server.
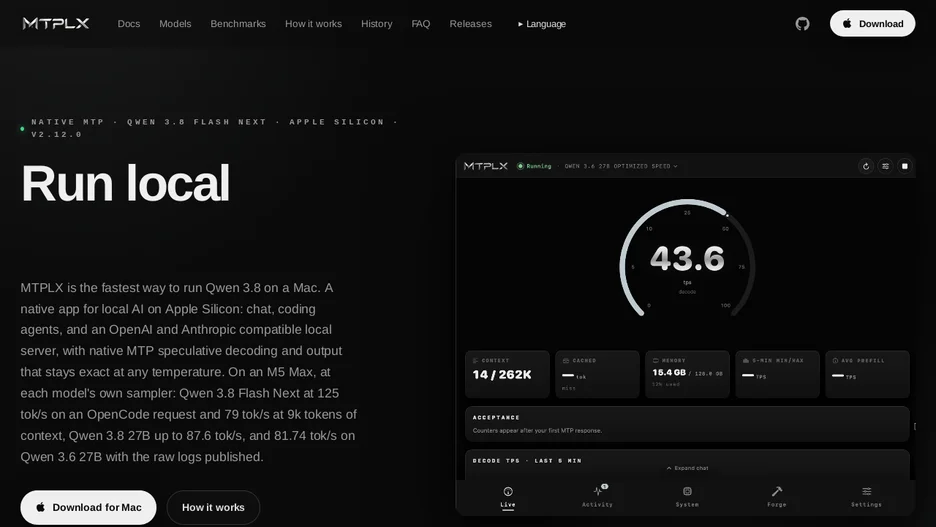
MTPLX runs local language models on Apple Silicon Macs using a model's own multi-token prediction (MTP) heads: the model drafts several tokens ahead of itself, one batched forward pass verifies the draft, and tokens are committed through exact rejection sampling with residual correction, so output matches the model's native sampling at any temperature rather than approximating it.
It supports Qwen 3.8 Flash Next, Qwen 3.8 27B, Qwen 3.6, Qwen 3.5, Gemma 4 and Prism ML's Ternary Bonsai 2 27B, and reports decoding roughly 1.6 to 2.24 times faster than plain decoding depending on the Mac and model, with a 27B model runnable on 16GB of memory. It exposes a local server compatible with the OpenAI and Anthropic APIs, so existing tools that speak either API can point at it directly.