

OMP NInfer
A packaging of a durable local inference server for the Qwen3.8 27B model on a single consumer NVIDIA GPU, built to resume a coding agent's session from saved state after the inference server restarts.
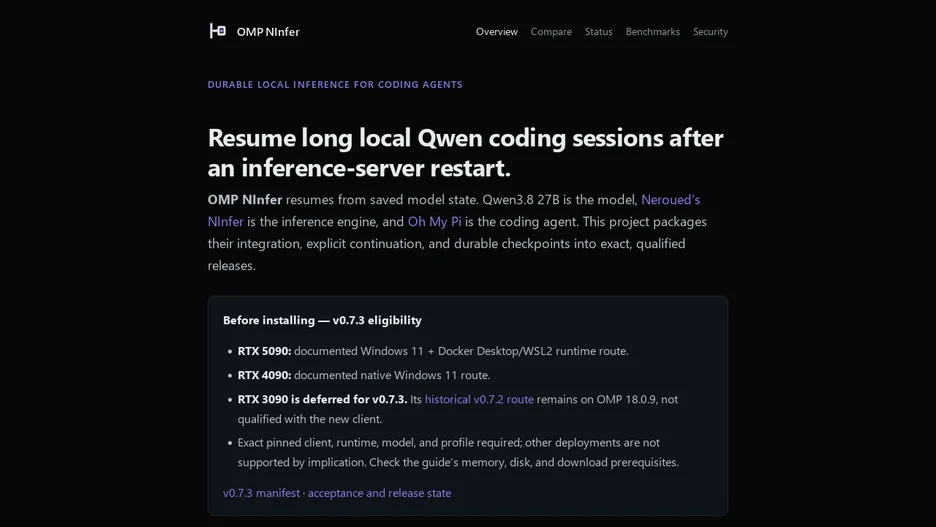
OMP NInfer packages the Neroued NInfer inference engine serving a Qwen3.8 27B model for the Oh My Pi coding agent, adding explicit session continuation and durable checkpoints so a long local coding session can resume after the inference server process restarts, instead of losing its state. Each release is scoped to an exact, qualified combination of GPU, client, runtime and model profile; the current release targets one NVIDIA RTX 5090 or RTX 4090 card, documented for Windows 11 with Docker Desktop or WSL2, while RTX 3090 support is deferred to an older, separately maintained release line.
The project documents its endpoints as loopback-only and bearer-authenticated, failing closed rather than falling back to a cloud service, and ships hash-pinned release artifacts with checksums. It provides continuous integration status, benchmark and context-length badges, and a recorded demo of a bug fix and stateful follow-up from an earlier release.