

OpenModel
A gateway-first local model runtime and CLI that pulls, runs, and serves GGUF or Ollama models behind an OpenAI-compatible endpoint, with a dashboard, token telemetry, and an optional GPU capacity marketplace.
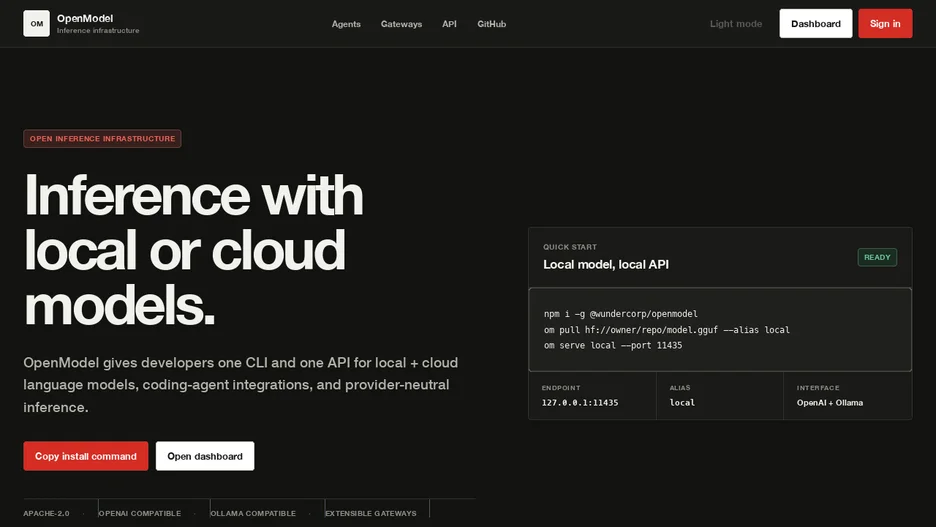
OpenModel is a gateway-first local model runtime distributed as an npm package, paired with a dashboard, a marketing site, and a separately deployable cloud API. Its CLI can pull models from Hugging Face GGUF files, direct artifact URLs, Ollama references, or contributed gateways; run them through llama.cpp or Ollama runtimes; and serve them behind OpenAI-compatible and Ollama-compatible local endpoints exposing chat completions, model listing, and installation and runtime-status routes.
Beyond local serving, it includes a worker enrollment and provider system for publishing GPU capacity and pricing, with heartbeats, assignment processing, earnings, and payouts, and a hyperscaler-style control plane with reservations, metering, fee snapshots, disputes, and settlement states, alongside a dashboard GPU marketplace showing worker health, earnings, and public availability. It also offers isolated agent VMs called BuilderStudio boxes, with Claude Code and Codex available as secondary agent options inside them.
Authentication uses OIDC device login for the CLI and OIDC Authorization Code with PKCE for the website; the cloud layer deploys to AWS Lambda and API Gateway, with the website on S3 and CloudFront.