

OSCAR
OSCAR is a quantization method that compresses the key/value cache used during LLM inference down to 2 bits, cutting KV-cache memory by about 8x compared with BF16 while speeding up decoding and throughput.
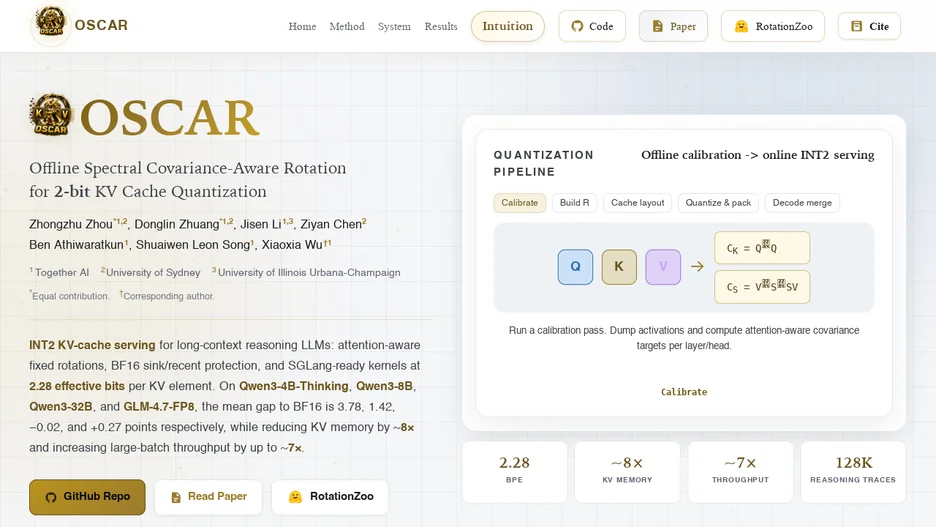
OSCAR (Offline Spectral Covariance-Aware Rotation) quantizes the key/value cache in large language model inference to 2 bits. It captures Q/K/V activations on a calibration set, estimates attention-aware covariance structures for K and V offline, and derives per-layer rotations and clipping thresholds so quantization aligns with the directions attention actually uses. Only a small BF16 sink and a recent window stay at higher precision; the rest of the cache is stored in INT2.
The project reports about 8x less KV-cache memory than BF16, along with higher decoding throughput at large batch sizes and faster batch-size-1 decoding through an accompanying attention kernel. OSCAR is integrated into the SGLang and llama.cpp inference engines, and it ships a rotation zoo of precomputed calibration rotations so users do not have to recompute them for supported models.