

Picchio
A benchmarking tool that shows exactly where a local LLM ran, CPU or GPU and on which layers, alongside prefill, decode, memory and power measurements.
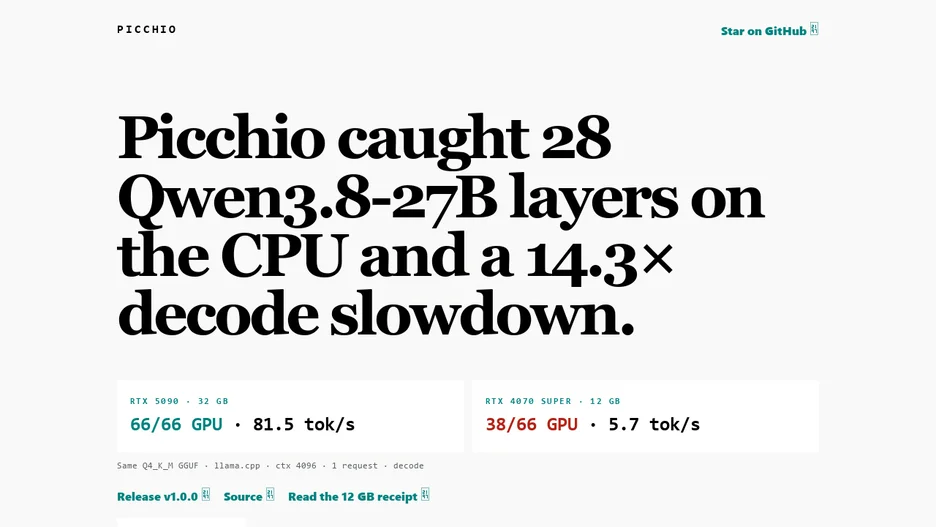
Picchio reports an "inference placement receipt" joining an engine's layer placement, the system's GPU readings, and separate speed measurements, so it can show that a model answering at a usable speed is still running partly on the CPU rather than fully on the GPU. It ships as a single-file, dependency-free download using only the Python standard library, running on macOS, Linux and Windows.
With no arguments it discovers Ollama tags, local GGUF files, and models cached by Hugging Face or LM Studio, then runs three measurement passes; it can also be pointed directly at a model file, a model tag, or a running server. A "plan" mode checks whether a model fits before downloading it, at a chosen context length and KV cache type; a "guard" mode watches a running command, model or server and reports the moment it leaves the GPU; and a "compare" mode diffs two runs and reports the first setting that changed between them.