

prima.cpp
A distributed implementation of llama.cpp that spreads a 30 to 70 billion parameter model's layers across ordinary home devices, such as laptops, desktops, phones and tablets, keeping memory pressure low without requiring a GPU on every device.
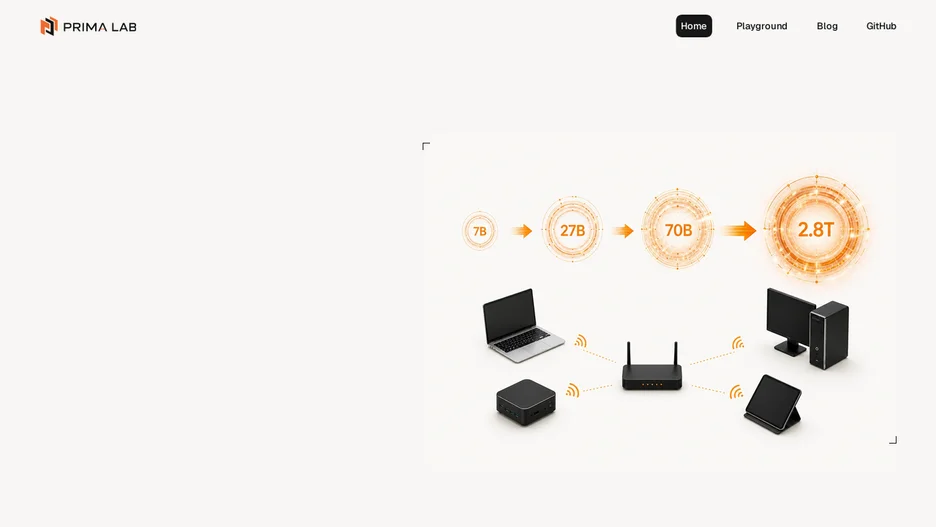
prima.cpp is a distributed version of llama.cpp built to run large language models, such as QwQ-32B, Qwen 2.5-72B, Llama 3-70B or DeepSeek R1 70B, across a cluster of everyday devices rather than one high-end machine. Devices can mix operating systems and hardware, with or without a GPU, and the project reports keeping memory pressure below 10% so a device stays usable for other tasks while running inference.
It reports being substantially faster than plain llama.cpp on the same hardware in its published comparisons, with example clusters mixing an Apple Silicon laptop, an Intel desktop and a phone running a simulated Linux environment, communicating over the network with device selection.
The project is research-oriented and documents its device configurations and token-latency comparisons in detail so results can be reproduced on similar hardware.