

PRISM
An open, executable benchmark that scores how well large language models write 1C:Enterprise (BSL) code, judging generated code on syntax, meaning, optimization and platform fit by actually compiling and running it.
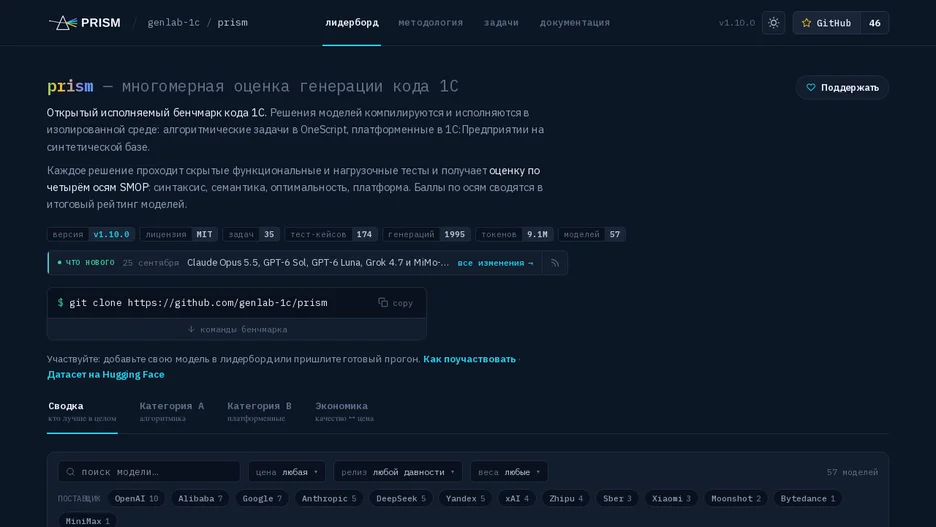
PRISM measures how well AI models write code for the 1C:Enterprise 8 platform by running the generated BSL code through a compiler, tests and execution against a real configuration, rather than a single pass or fail score. It scores results along four axes it calls SMOP: syntax, meaning, optimization and platform fit, and publishes an interactive leaderboard comparing models such as Claude, GPT, Gemini, DeepSeek, YandexGPT and GigaChat.
Model access goes through adapters, including OpenRouter and any OpenAI-compatible endpoint such as a local Ollama or vLLM server, so adding a new provider is a single adapter file. A dry-run mode estimates cost before a run, a mock mode exercises the pipeline without any network calls or spend, and a budget cap, checkpointing and retries support large, unattended runs.
Tasks are tagged by skill area so weaker spots in a model's code are visible, and the benchmark is explicitly still growing its task bank through community-submitted tasks. It is written in Python under the MIT license.