

ProgramBench
A benchmark and CLI that tests whether AI agents can architect and implement a complete codebase reproducing a compiled binary's behavior, given only that binary and its documentation.
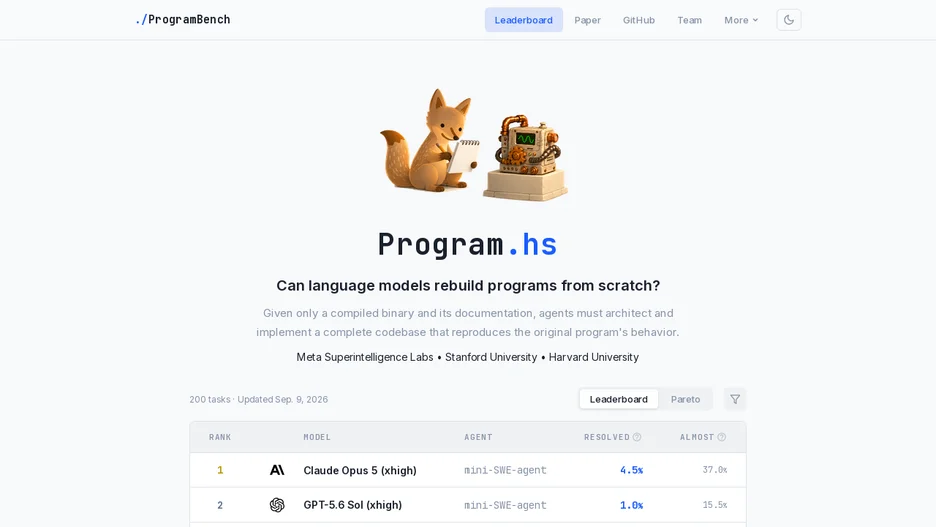
ProgramBench evaluates whether an AI coding agent can rebuild a program from scratch: given only a compiled binary and its documentation, the agent must design and implement a codebase that reproduces the original program's behavior. The project provides a Python package, programbench, installable with uv, pip, or uvx to run without installing, along with a public leaderboard for submissions and a website and paper describing the benchmark's design.
A reference baseline uses mini-swe-agent, a minimal software-engineering agent, invoked through uvx --from mini-swe-agent mini-extra programbench or by installing mini-swe-agent separately, with its own documentation describing how the baseline is run against the benchmark.
The project is developed and released by Facebook (Meta) AI Research.