

PureDocBench
A benchmark dataset of 1,475 document pages that evaluates document-parsing and OCR models on text, formulas, tables and reading order, matched across clean, digitally degraded and real-world scanned versions of the same pages.
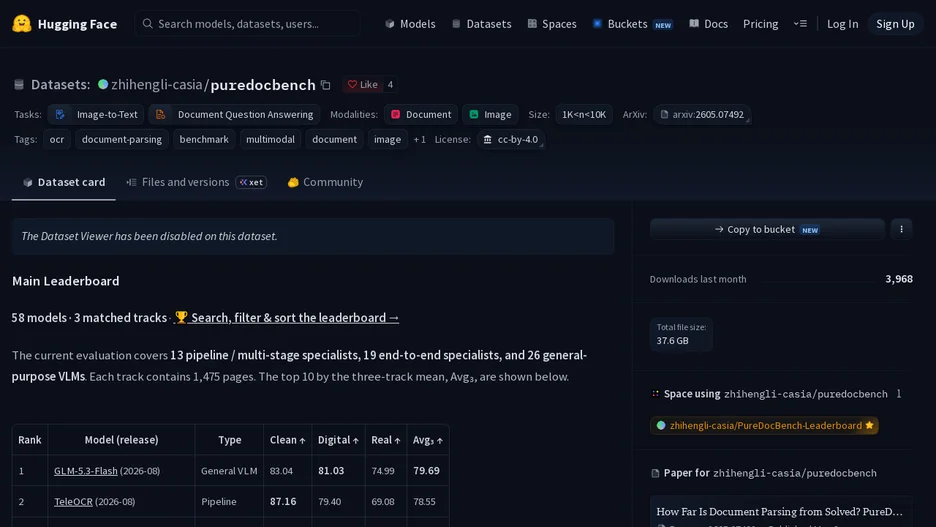
PureDocBench is built from pages generated from an HTML and CSS source, which also provides the structured ground-truth annotations for each page. Each page exists in three matched versions, Clean, Digital and Real, sharing the same content and references so results can be compared directly across image conditions rather than across different documents.
The published leaderboard evaluates pipeline and multi-stage document-parsing specialists, end-to-end specialists, and general-purpose vision-language models, reporting an overall score per track and their mean. The current release covers 1,475 pages across 10 domains and 66 subcategories, with 4,425 matched images, and the maintainers periodically refresh the ground truth and results as new models are released.
The dataset and results are hosted on Hugging Face, and the project is written in Python.