

qMLX
A Qwen-specialized fork of MLX adding disk-backed KV-cache checkpointing for hybrid attention models, letting a 122-billion-parameter model stay responsive across long conversations on Apple Silicon.
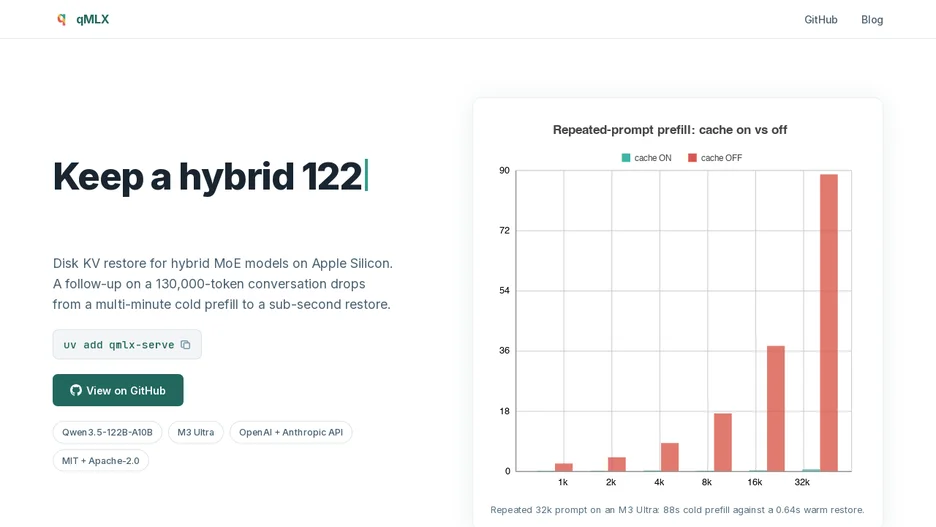
qMLX is a custom inference engine, forked from MLX, for serving the hybrid Qwen3.5-122B-A10B model on Apple Silicon. About three-quarters of that model's layers are recurrent DeltaNet layers whose state cannot be rewound to an earlier position, so a standard in-memory prefix cache misses almost every time; qMLX instead checkpoints attention key-value state to SSD and restores it on the next turn, making disk the only cache reuse tier rather than a fallback.
It adds a matchable-aware disk-cap eviction policy so a checkpoint the next turn will need is not evicted by unrelated writes, reports phase-split metrics that separate real decode and prefill throughput from cached tokens, and logs the exact token where a prefix-cache match diverges to make cache bugs diagnosable. On measured hardware, a repeated 32,000-token prompt dropped from 88 seconds of cold prefill to under a second with the disk restore. It is built specifically for the Mac Studio and unified memory rather than for portability, and runs a single user session at a time.
It extends MLX and its documentation covers installation and design principles for Apple Silicon.