

RAG Engine
A full-stack retrieval-augmented-generation template covering authentication, knowledge-base management, document parsing and vectorization, hybrid retrieval, streaming chat and evaluation in one repository.
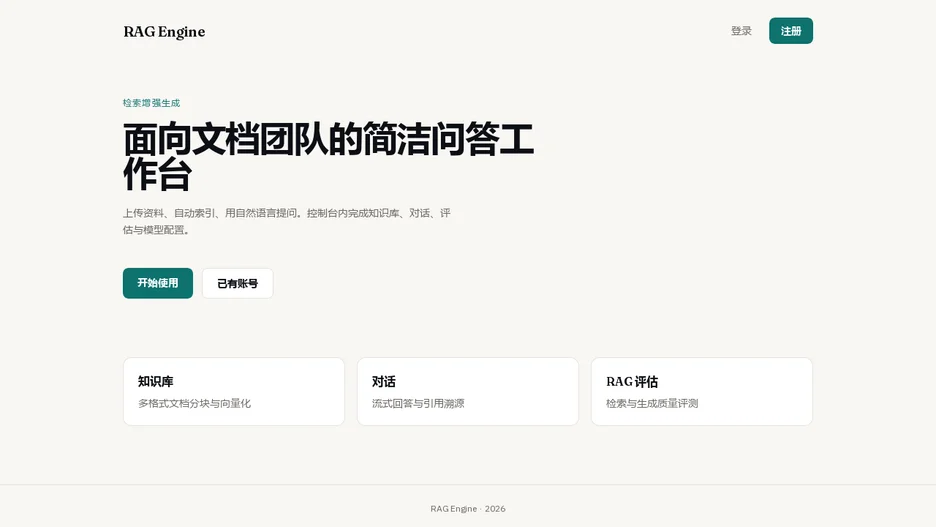
RAG Engine runs the whole RAG pipeline end to end: authentication, knowledge-base and document processing, vector retrieval, streaming chat over Server-Sent Events, and optional automated evaluation, meant as a starting point for further development rather than a finished product.
A configurable retrieval pipeline controls query rewriting, hybrid retrieval combining dense search with BM25 and reciprocal rank fusion, multi-path recall, reranking and parent-child chunk expansion, falling back to plain vector search with a top-k cutoff when these are turned off. LLM and embedding endpoints and keys are stored in the database rather than only in environment variables, so OpenAI-compatible APIs and local backends can be switched at any time.
Storage is split across MySQL for business metadata, Chroma for vectors, and MinIO for raw files. The backend is FastAPI with LangChain; the frontend is Next.js with React and Tailwind, deployed separately from the backend. It is MIT licensed.