

RAP: Retrieval-Augmented Personalization for Multimodal Large Language Models
Research code for teaching a multimodal language model to recognize and remember user-specific concepts through retrieval augmentation, so it can discuss a person's own subjects in later conversations.
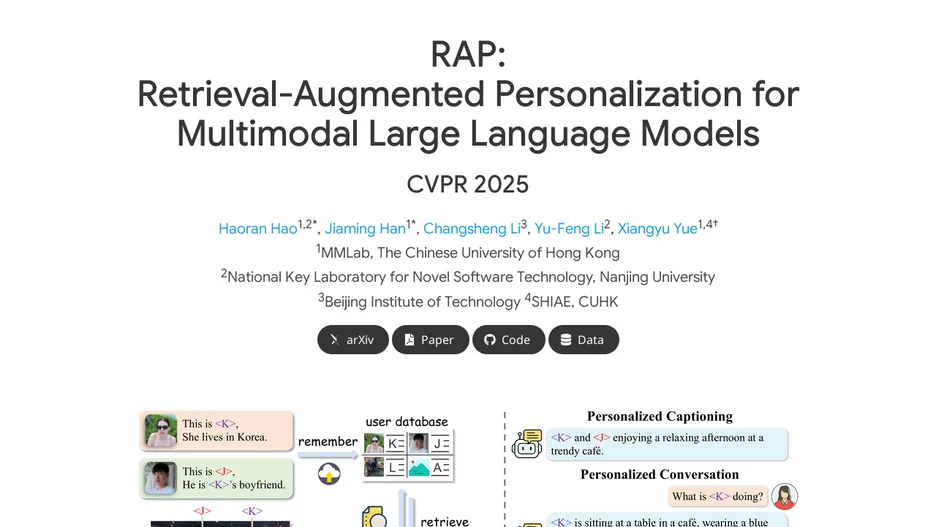
RAP-MLLM is the code release for a CVPR 2025 paper on retrieval-augmented personalization for multimodal large language models. It lets a user introduce concepts specific to them, such as a particular person or object, into the model through a retrieval database, so the model recognizes and reasons about those concepts in later multimodal generation tasks.
The repository includes installation instructions built around a conda environment, pretrained model weights on Hugging Face, a command-line demo that answers questions about an image using a personal concept database, training scripts using DeepSpeed, and an evaluation pipeline for image captioning and other benchmarks against comparable methods.