

SlopTotal
A self-hosted AI-text detector that runs 23 independent detection engines on CPU and combines their scores into one calibrated forensic result, with published accuracy figures and its own documented failure modes.
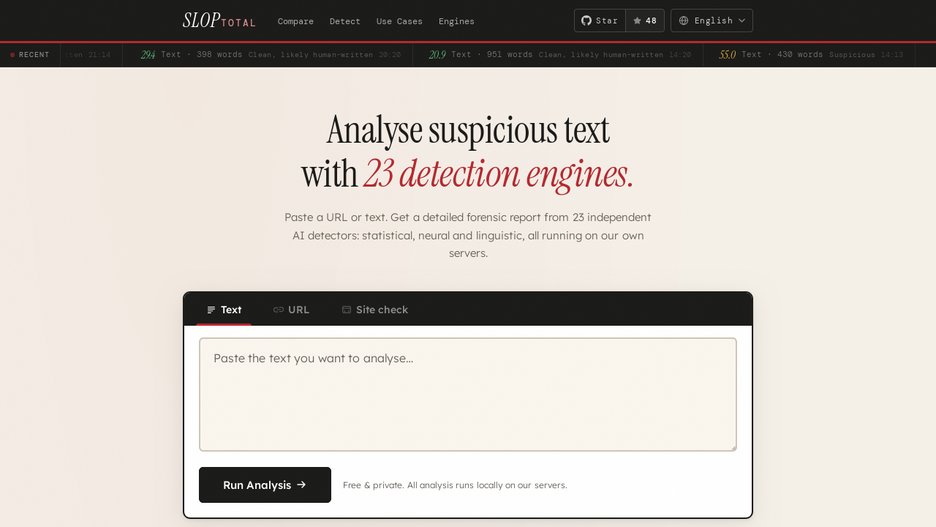
SlopTotal scans text or a URL with 23 detection engines running in parallel, neural classifiers, statistical tests and linguistic heuristics, streaming results as each engine finishes and combining them into a calibrated score. Everything runs on the user's own hardware; no data is sent to third parties.
Measured accuracy is published against two corpora: a multi-domain set of news, book prose, poetry and academic abstracts with AI text from several model families, and a literary control set of public-domain prose predating language models by a century or more, included because any high score there must be an error. The project reports an overall AUC of 0.974, and states that short text under roughly 80 words is unreliable, heavily hand-edited AI text loses its fingerprint, and source code is outside what the engines can reliably classify.
It requires Python 3.10 or newer, runs on CPU with no GPU required, needs at least 4 GB of RAM, and downloads about 2 GB of models on first run.