

Squish
A local inference daemon for running LLMs on Apple Silicon that exposes an OpenAI- and Ollama-compatible API, built for fast model loading and low latency.
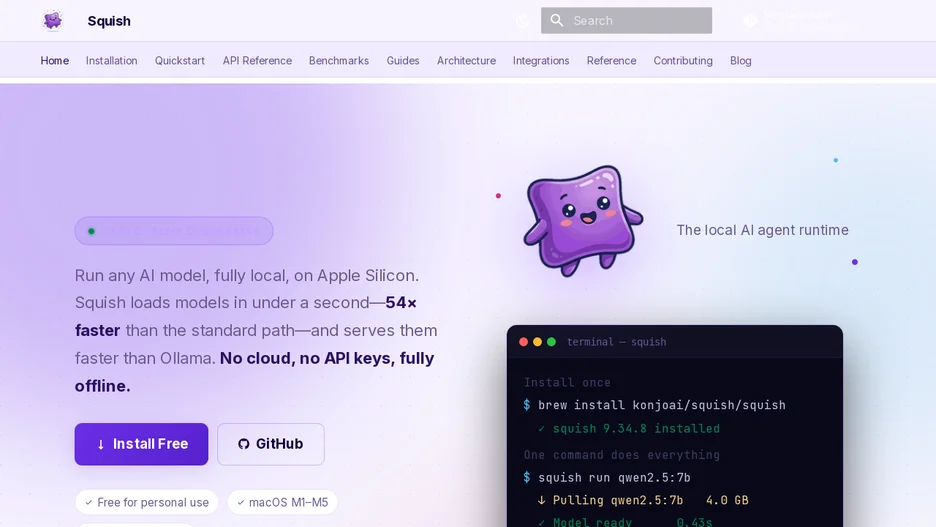
Squish is a persistent inference daemon for Apple Silicon that separates how model weights are stored from how they run: weights are stored compressed and Metal-native, mapped directly into unified memory, skipping the dtype-conversion step the project says slows other loaders. It runs fully offline, needs no cloud connection or API keys, and exposes one OpenAI- and Ollama-compatible endpoint.
On an Apple M3 MacBook Pro with 16GB RAM, the project's own thermally-controlled benchmarks report faster cold starts, higher decode throughput, lower inter-token tail latency, lower peak RAM and faster full-response time than Ollama serving the same Qwen2.5-7B-Instruct model, with a smaller margin on completely unique, non-cached prompts than on repeated ones.