

SWE-bench
A benchmark that evaluates whether a language model can generate a patch resolving a real GitHub issue, given the codebase and the issue description.
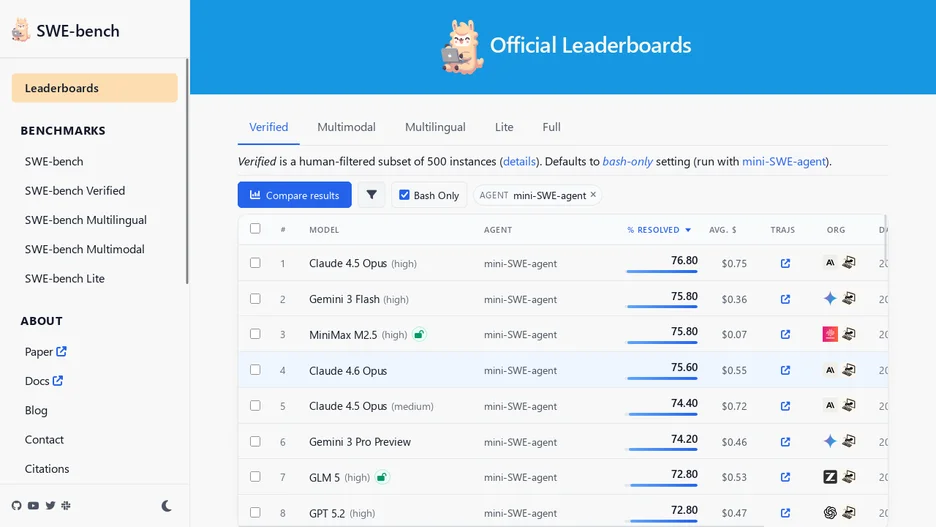
SWE-bench collects real-world GitHub issues, and given a task consisting of a codebase and an issue, requires a model to generate a patch that resolves it, with evaluation run inside Docker for reproducibility. A curated subset, SWE-bench Verified, contains 500 problems that real software engineers have confirmed are solvable, produced with OpenAI's Preparedness team, and SWE-bench Multimodal extends the benchmark to visual software domains, with a second version of that multimodal set fully open-sourced with 480 tasks for local evaluation.
The dataset is distributed through the Hugging Face datasets library, a companion cloud-based evaluation tool called sb-cli supports submitting runs to the project's public leaderboards, and evaluations can also run entirely in the cloud through Modal. A separate related project, SWE-agent, is built on top of this benchmark.
It is written in Python and distributed under the MIT license.