

Terminal-Bench
A benchmark suite and execution harness for testing how well AI agents complete real-world, end-to-end tasks in a real terminal environment, such as compiling code, training models or setting up a server.
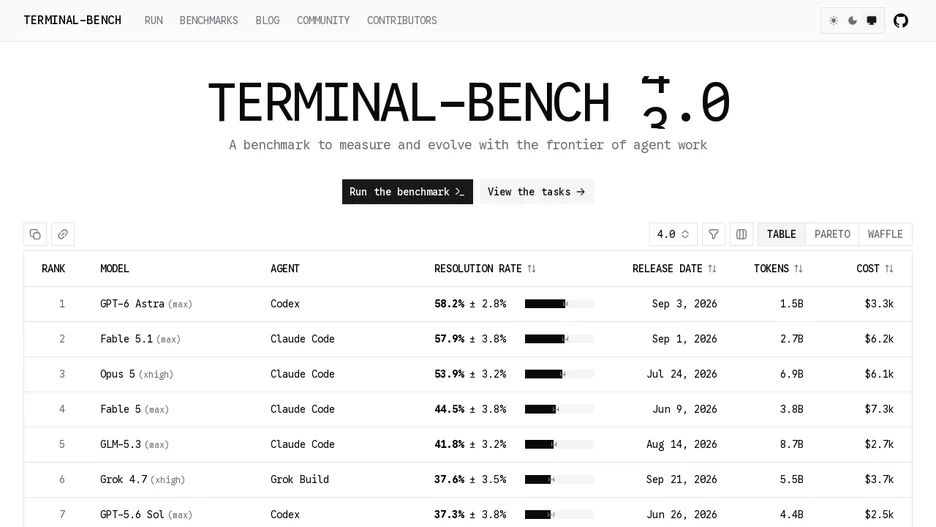
Terminal-Bench is a benchmark for evaluating AI agents in real terminal environments, covering practical end-to-end tasks such as compiling code, training models and setting up servers rather than narrow, single-step problems. It provides a reproducible task suite together with an execution harness that connects a language model to a sandboxed terminal.
Each task includes an English-language instruction, a test script that checks whether the agent completed it successfully, and a reference solution. The benchmark is currently in beta with about 100 tasks, distributed as a pip-installable package with its own command-line tool, and results can be submitted to a public leaderboard against a fixed, versioned task set. A newer companion framework, Harbor, is recommended for running the next version of the benchmark.