

Tightwad
Tightwad pools CUDA and ROCm GPUs across separate machines and speeds up local LLM inference with application-layer speculative decoding, sitting as a drop-in proxy in front of an existing model endpoint.
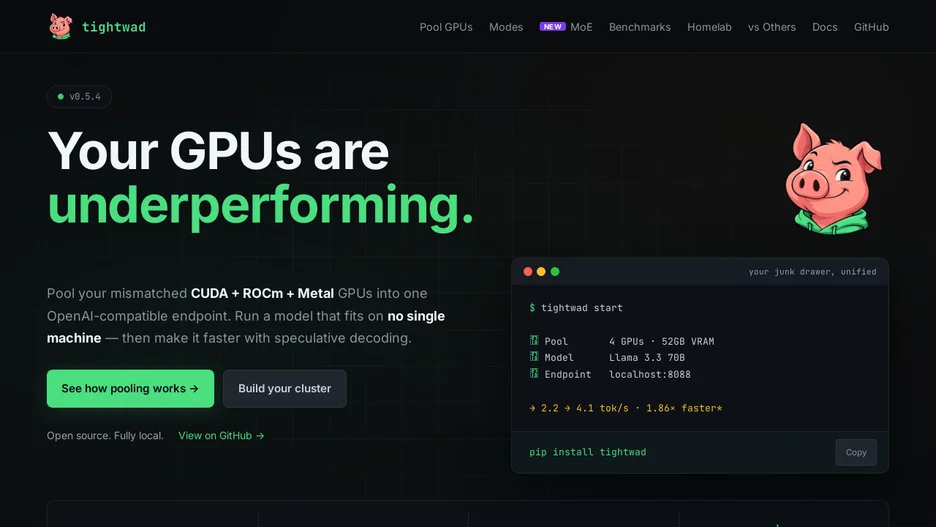
Tightwad is a mixed-vendor GPU inference cluster manager that combines two ideas: pooling CUDA and ROCm GPUs across different machines using llama.cpp's RPC support, and speculative decoding across those network-separated machines. A small model on one machine drafts tokens quickly, and a larger model on another verifies a batch of them at once, so the slow model does less serial work.
From a user's point of view nothing changes: the same chat application points at Tightwad's proxy port instead of directly at a model server, and the response is identical or statistically equivalent to what the large model alone would produce, just faster.
The project includes a setup guide aimed at AI assistants helping a user deploy it, covering hardware assessment, configuration and model selection.